7 rules for self-improving agent loops every AI engineer should know
By @Saboo_Shubham_ and @secchi_eliaWhen coding agents write the code, defining what's good is the real engineering job.Coding agents can now...
📝 摘要
本文由 Google Cloud 的 Shubham Saboo 和 Elia Secchi 撰写,核心论点是:当编码智能体(coding agent)可以自动编写代码时,定义"什么是好的"成为工程师真正的核心工作——指标(metric)才是你如今要编写的制品。文章介绍了 Google 开源的 agents-cli 工具及其基于 ADK 的自我改进循环(generate → grade → fix → compare),并提出保持循环诚实的 7 条规则。
核心概念: 智能体自我改进循环的盲区在于——循环可以自动化一切,唯独无法告诉你"更好"意味着什么;指标定义才是工程判断力的落脚点。
关键技术栈 / 关键要点:
- 指标即制品(The metric is what you now author) — 工程努力从制品上移到标准上,循环会重塑 prompt、代码和行为来拟合你奖励的任何东西
- agents-cli 工作流 —
eval generate生成 traces →eval grade评分(打破自我评判的循环性)→eval compare对比前后运行确认改进 - 自定义指标优于通用基准 — 保留规则、合规线、品牌语气等业务特定质量只能由自定义指标捕获,公共基准无法替代
- 7 条规则 — 从单 case 开始、让 judge 解释原因、确定性检查用代码、评分行为而非路径、flaky case 即发现、不让提议者移动标准、prompt 优化只做一次且放最后
- Eval 与可观测性是同一循环的两种采样 — 开发时叫 eval,生产时叫 monitoring,同一指标定义跨场景复用
- 反奖励黑客(reward hacking) — 降低阈值、编辑期望输出、静默丢弃 case 都会伪装成分数提升,held-out set 是防线
关键结论 / 实践建议: 从一个指标、一个 case、一个循环开始,不要一开始就追求完整评测套件;将指标定义保存在循环无法触及的地方,确保人类始终掌控"什么是好的"这一上游标准。
By @Saboo_Shubham_ and @secchi_elia
When coding agents write the code, defining what's good is the real engineering job.
Coding agents can now build and improve other agents. Write the instructions, run the agent, find where it fails, rewrite, repeat. That self-improving loop ships today. Automating it is most of what agents-cli, our open-source CLI and skills for building agents on Google Cloud, does.
But the loop has a blind spot.
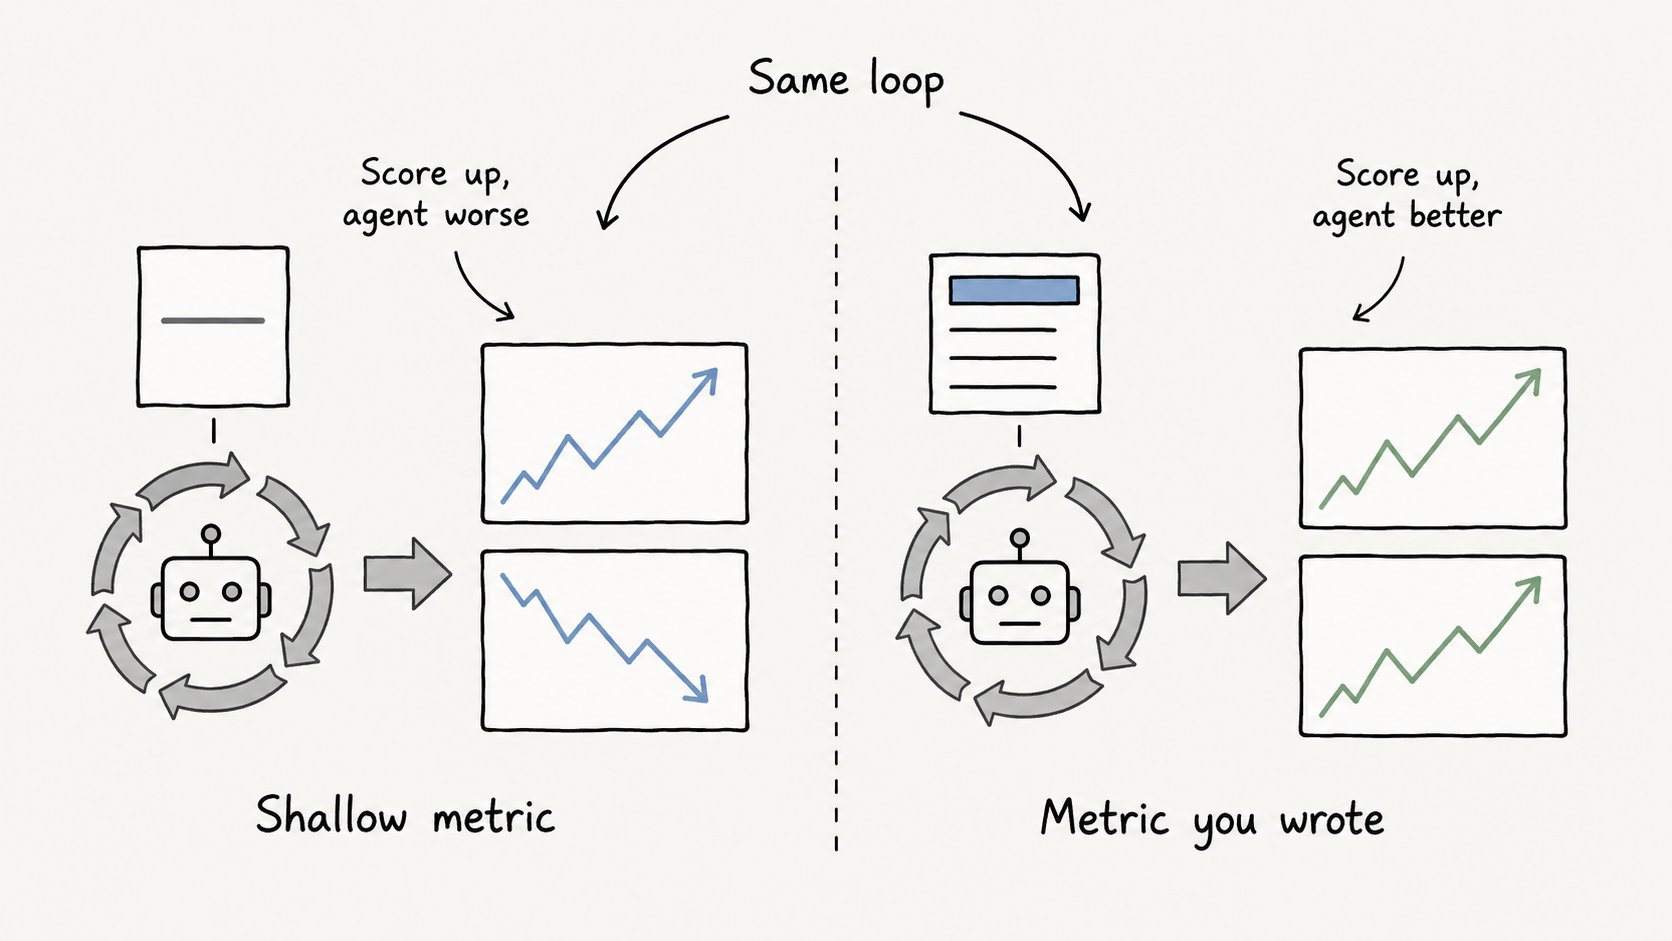
Give it a shallow target and it will optimize your agent into something that scores well and works worse. Then it reports success. Because by its own measure, it succeeded.
The loop can automate everything except telling you what "better" means.
The metric is the artifact you now write. Defining what good means, and measuring it well enough that a loop can improve toward it, is where the engineering judgment went. This article covers how the loop runs, where humans stay in control of it, and the seven rules that keep it honest.
The metric is what you now author
Software teams have always known you get what you measure. The loop makes it literal. It improves whatever number you give it, and nothing inside it can tell the difference between a target that reflects what you want and one that merely scores well.
We kept relearning this while building the tool. The metric sits upstream of the prompt, the code, and the behavior. The loop will reshape all three to fit whatever it rewards.
Every tooling advance has moved effort up a level. Assembly to compilers. Compilers to frameworks. This one moves it from the artifact to the standard.
Quality is specific, and it belongs to you
The definition of good that matters is rarely the one a public benchmark measures. It's the refund policy. The escalation rule. The compliance line. The tone your customers recognize.
A general model does not know these things, and a general test will not check them.
Consider a support agent whose rule is to offer the retention path before confirming a cancellation. A model can follow that rule in its reasoning and still drop it from the final reply. We've watched agents fail in exactly this shape: internal state correct, right tool called, and the final message to the user echoing a stale value anyway. Nothing crashes. The output reads fine on a skim. The answer the user receives is wrong.
Only an evaluation that grades the reply, not the reasoning, catches this. And no public metric knows your retention rule exists. So you define your own: a custom metric, `retention_offered`, that returns 0 or 1 and a one-line reason for the verdict. Written down, that definition is yours to own, version, and sharpen as new failures come in.
The loop in practice
agents-cli turns the loop into a few commands, run over agents built with the Agent Development Kit (ADK). Install it into your coding agent:
agents-cli turns the measure-and-improve loop into a few commands, run over agents built with the Agent Development Kit (ADK). Install it into your coding agent:
uvx google-agents-cli setup
Then describe what you want measured.
Take the support agent from earlier. No public metric captures its retention rule, so you define your own: a custom metric, retention_offered, that returns 0 or 1 and a one-line reason for the verdict. That definition is the standard everything else is judged against.
The coding agent starts by running your agent over a set of cases to produce traces:
agents-cli eval generate \
  --dataset tests/eval/datasets/cancellation_cases.json \
  -o artifacts/traces/
The tempting shortcut at this point is to let the coding agent read its own output and decide whether it passed. An agent asked to judge its own reply grades it optimistically, and the failures that matter are exactly the kind it waves through.
Grading breaks that circularity. Every trace is scored against your metric, a standard the coding agent cannot move, so a fix is judged by something other than what proposed it:
agents-cli eval grade \
  --traces artifacts/traces/ \
  --config tests/eval/eval_config.yaml
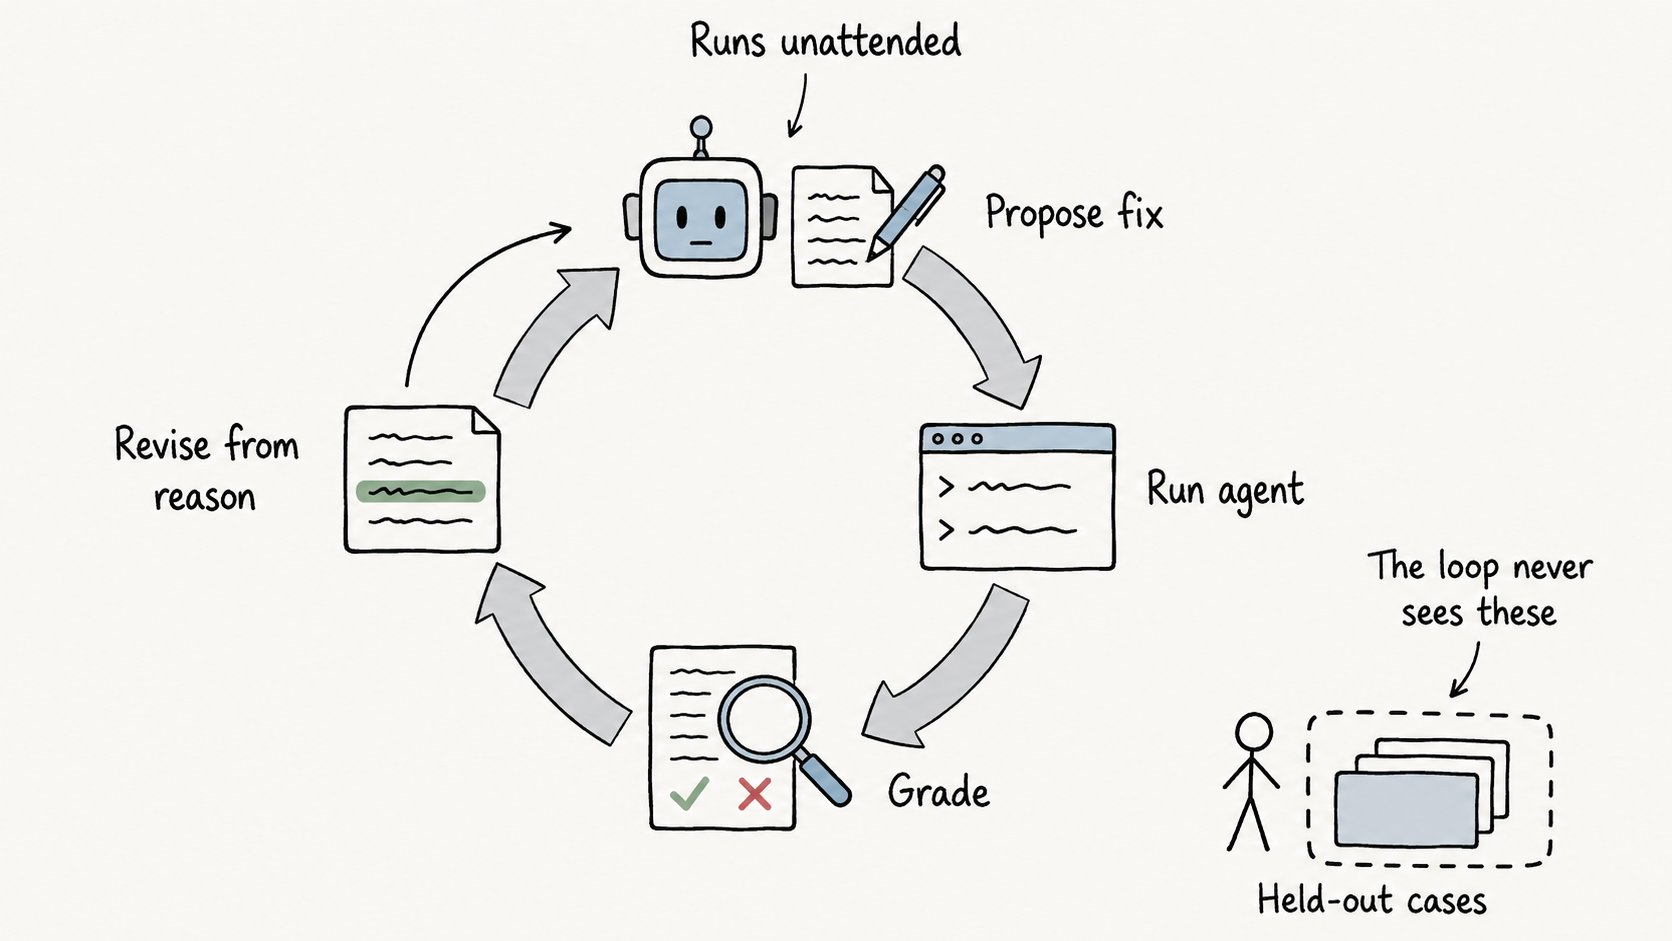
Now the loop can improve on its own. Each failing case comes back with the metric's own reason, and that reason is the direction for the next attempt. The coding agent reads it, edits the agent's instructions, and re-runs. Then it compares the two runs to confirm the change helped without breaking anything else:
agents-cli eval compare \
  artifacts/grade_results/results_baseline.json \
  artifacts/grade_results/results_after_fix.json
That cycle (propose a fix, grade it, revise from the reason) is the entire optimization. It runs unattended between your checkpoints: you set the target and hold the held-out set, and everything the loop needs to steer by is already in the metric you wrote.
The 7 rules for self-improving loops
Automating the loop was the easy part. The hard part was keeping humans in control of something designed to run without them. These seven rules are how, and they're now built into the agents-cli skills themselves.
Rule 1: Start with one case, not a suite. One failing case tells you what to fix next. Twenty tell you nothing. Expect five to ten iterations before it passes. That's normal. Add the next case only once it holds.
Rule 2: Make judges explain themselves. A number says you failed. The reason says what to change, and the reason is what the next iteration gets written from. Deterministic checks are exempt, since the assertion is its own explanation.
Rule 3: Use code wherever the answer is deterministic. "Did it call the retention tool before confirming?" is a Python function. Exact, free, no judge variance. Save the judge for tone, completeness, whether an explanation holds up.
Rule 4: Score behavior, not paths. An agent that geocodes before checking the weather isn't wrong. Exact-match trajectories end up measuring how much the agent changed rather than how good it is.
Rule 5: Treat a flaky case as a finding. A score that moves between identical runs means your agent is non-deterministic in a way you hadn't noticed, or your judge is. Run the case a few times and see which one moves. Deleting it removes the evidence, not the behavior.
Rule 6: Never let the proposer move the bar. A bar moves three ways: lowered threshold, edited expected output, quietly dropped case. All three look like an improving score. This is what the held-out slice is for. A real gain shows up there too. A gamed one doesn't.
Rule 7: Auto-optimize once, at the end. Prompt optimization is expensive and only fixes wording, never a missing tool call. Looping on it spends hours rediscovering what the failure reasons already said.
It compounds over time
The payoff grows over time. The eval set turns into a durable record of what your organization means by quality, running on demand in development and in CI on every change, always against one definition of good.
Past deployment, the same definition keeps working. In development you call it eval. In production you call it monitoring. It's the same metric.
A deployed agent already exports its execution traces. With prompt-response logging, its prompts and replies land in BigQuery, so running your metric over that table is the same grading step applied to real traffic instead of a written dataset.
Eval and observability turn out to be one loop sampled two ways. Over the cases you wrote, and over the conversations you didn't.
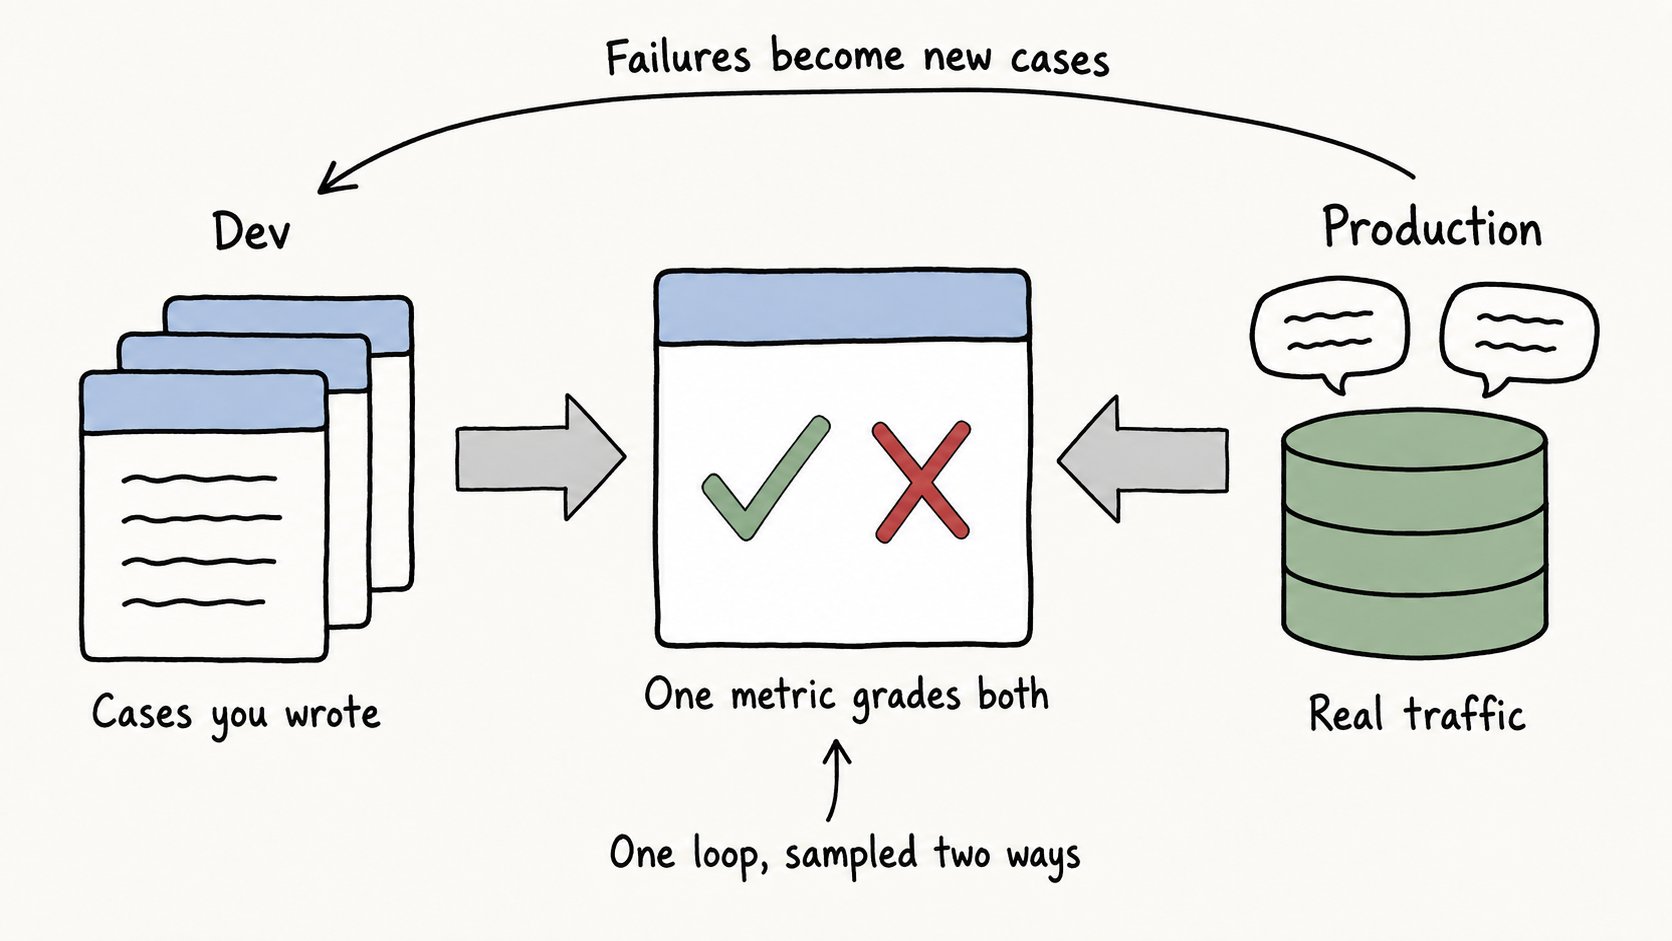
Every production exchange that goes wrong becomes a new case, graded by the same metric, guarding against that regression from then on. Treat each grade as a signal about direction rather than ground truth, and trust the movement between runs more than any single score.
Get started today
One rule sits above the other seven. The coding agent does the iterating. It writes the prompt, runs the agent, finds the gap, and closes it. What it cannot generate is the definition of good it optimizes toward.
Write that down before you start the loop. And keep it somewhere the loop cannot reach.
Then start today with agents-cli, and start small:
uvx google-agents-cli setup
Pick one behavior your agent must get right. The retention rule. The compliance line. The thing you currently check by reading transcripts. Write it as a metric that returns pass or fail with a one-line reason. Add one failing case. Point your coding agent at it and let the loop run.
That's the whole first session: one metric, one case, one loop. Full docs at google.github.io/agents-cli.
Your agent doesn't have to be perfect. It has to be improvable.