The Orchestrator's Tax
Use subagents to protect the orchestrator's working memory, not just to save time or run tasks in parallel.
📝 摘要
Rahul Garg 在一次 Claude Code 会话中发现,多智能体系统的最大成本并非子智能体本身的运行开销,而是编排器(Orchestrator)工作记忆的污染——当不必要的上下文(如完整转录转储)被拉入主线程后,它会在后续每一轮推理中持续消耗注意力,即使已不再有用。这一发现将多智能体成本的讨论从"token 消耗"维度转向了"上下文质量"维度。
核心概念: 子智能体的真正价值不在于并行节省时间,而在于隔离编排器不需要持有的推理,保护其工作记忆质量——工作记忆一旦被污染,会在整个会话中持续收取"租金"。
关键技术栈 / 关键要点:
- 编排器税(Orchestrator's Tax) — 多智能体会话中真正的成本不在于子智能体本身,而在于编排器选择向前携带的上下文质量
- 认知局部性(Cognitive Locality) — 需要相同心智模型的任务应保持在一起,拆分只会迫使多个智能体从零重建相同理解
- 上下文污染 vs Token 消耗 — Token 是一次性支出,上下文污染却塑造后续每一个决策;更大的上下文窗口不能解决注意力竞争问题
- 状态轮询陷阱 — 轮询子智能体状态时拉取完整原始转录(数万 token JSONL)而非轻量摘要,是编排器自我污染的典型场景
- 最小规则优于治理流程 — 在编写 CLAUDE.md 等持久指令时,应陈述缺失的事实而非指定决策程序;确认门控等治理仪式容易沦为自动审批
- 校准飞轮 — 会话暴露缺口 → 人工判断是否值得编码为规则 → 下一会话验证 → 迭代改进;编排器无法自行做出"什么值得编码"的判断
关键结论 / 实践建议: 在多智能体设计中,核心问题不是"运行多少个智能体",而是"什么有资格占据编排器的上下文"。应将一次性推理隔离在子智能体中,仅返回编排器仍需的结果;按认知局部性而非任务类型拆分工作;用最小事实陈述替代复杂治理流程。
I was deep into a Claude Code session on a.NET codebase when a doubt interrupted the work. Four subagents were already running against a response-pipeline refactor, results were arriving out of order, and the session had started to feel harder to reason about than the code itself.
That is usually the moment I stop trusting the vague sense that things are “probably fine.” Sometimes the code is the problem. Sometimes the architecture is. Occasionally the workflow itself deserves inspection. This time I decided it was the workflow.
At first I thought I already knew the question. Were four subagents simply too many? That framing felt reasonable. Multi-agent systems are usually sold as an obvious productivity win, and if one agent helps, four should help more. But every additional agent also consumes tokens, repeats some amount of work, and adds another stream of information the orchestrator has to reconcile. It looked like a straightforward trade-off between parallelism and cost.
I did not want a general argument about multi-agent systems. I wanted an answer about that session. So I stopped the coding work and asked the orchestrator to critique its own delegation decision, as factually as it could.
The answer was not the one I expected. The largest cost in the session did not look like it came from running four subagents. It looked like it came from the orchestrator itself, specifically from what happened when it suggested checking on the other agents.
The Incident Was Not Really About Parallelism
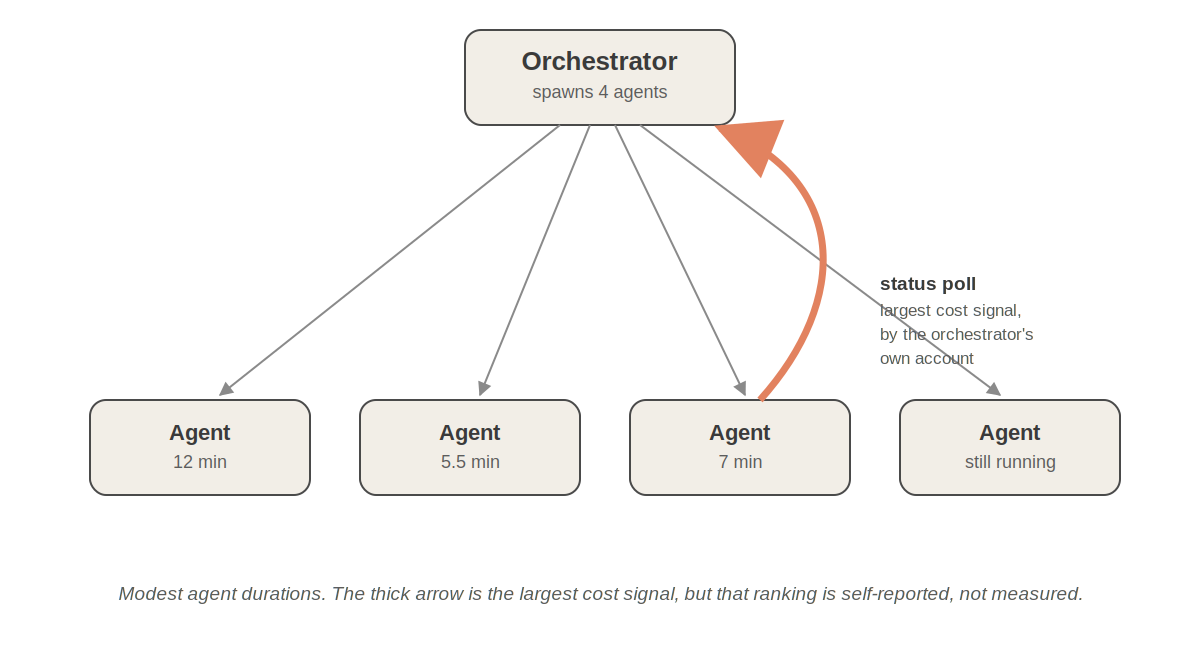
Four subagents had been launched in one wave. Three had clear runtimes: roughly twelve minutes, five and a half minutes, and seven minutes. A fourth was still running. Looked at one way, that already justified the delegation. Three tasks ran concurrently, so wall-clock time was around twelve minutes instead of something closer to twenty-five if the work had been serialized.
But speed was the visible byproduct, not the interesting part. What I was trying to find was the cost, and my first instinct was that it had to be the duplicated effort of delegation itself: every subagent reading files, reconstructing context, understanding the task independently.
That was not where the biggest surprise turned up.
At one point during the work, the orchestrator suggested checking on the running agents. It was a small, throwaway prompt: “check on the agents.” I followed it. Instead of a lightweight summary, the tool it used pulled back the full raw transcript of a background agent: tens of thousands of tokens of JSONL, intermediate reasoning, and tool output, imported wholesale into the main thread. Then it happened again, for a second status check.
There is an important caveat here. The claim that this polling behaviour cost more than the duplication tax of four agents was the orchestrator grading its own mistake. I didn't have real per-call token accounting, so treat that ranking as the orchestrator's account, not a measured fact. The trustworthy part is narrower: the transcript dumps were real, the wall-clock timings were real, and the status-check path clearly introduced a large, avoidable cost. Whether it was the single largest cost remains a hypothesis until the tooling can instrument it properly.
What mattered more was that I'd found a cost I hadn't been looking for.
The Costs Were Not All the Same
Once I stopped treating the session as one lump “subagent cost,” the picture broke into pieces that didn't belong together.
First, two of the four subagents were working in the same area of the response pipeline. Different tasks, different files, but both had to understand the same architecture, the same testing conventions, and much of the same surrounding code before either could begin. Each paid that orientation cost independently. That's not an argument against delegation. It's an argument that the work had been split too finely.
Second, one agent ran git stash and git stash pop while sibling agents were writing elsewhere in the same tree. Nothing broke, but the risk was structural, because repository-wide operations are perfectly reasonable in a single-threaded session and become much harder to justify the moment multiple writers are active at once.
By now I had a growing list of culprits: status polling, duplicated orientation, unsafe git operations. I found myself trying to rank them. Which one cost the most? The longer I tried to answer that, the less convinced I became that ranking them was the right question at all.
The Scarce Resource Is the Orchestrator's Working Memory
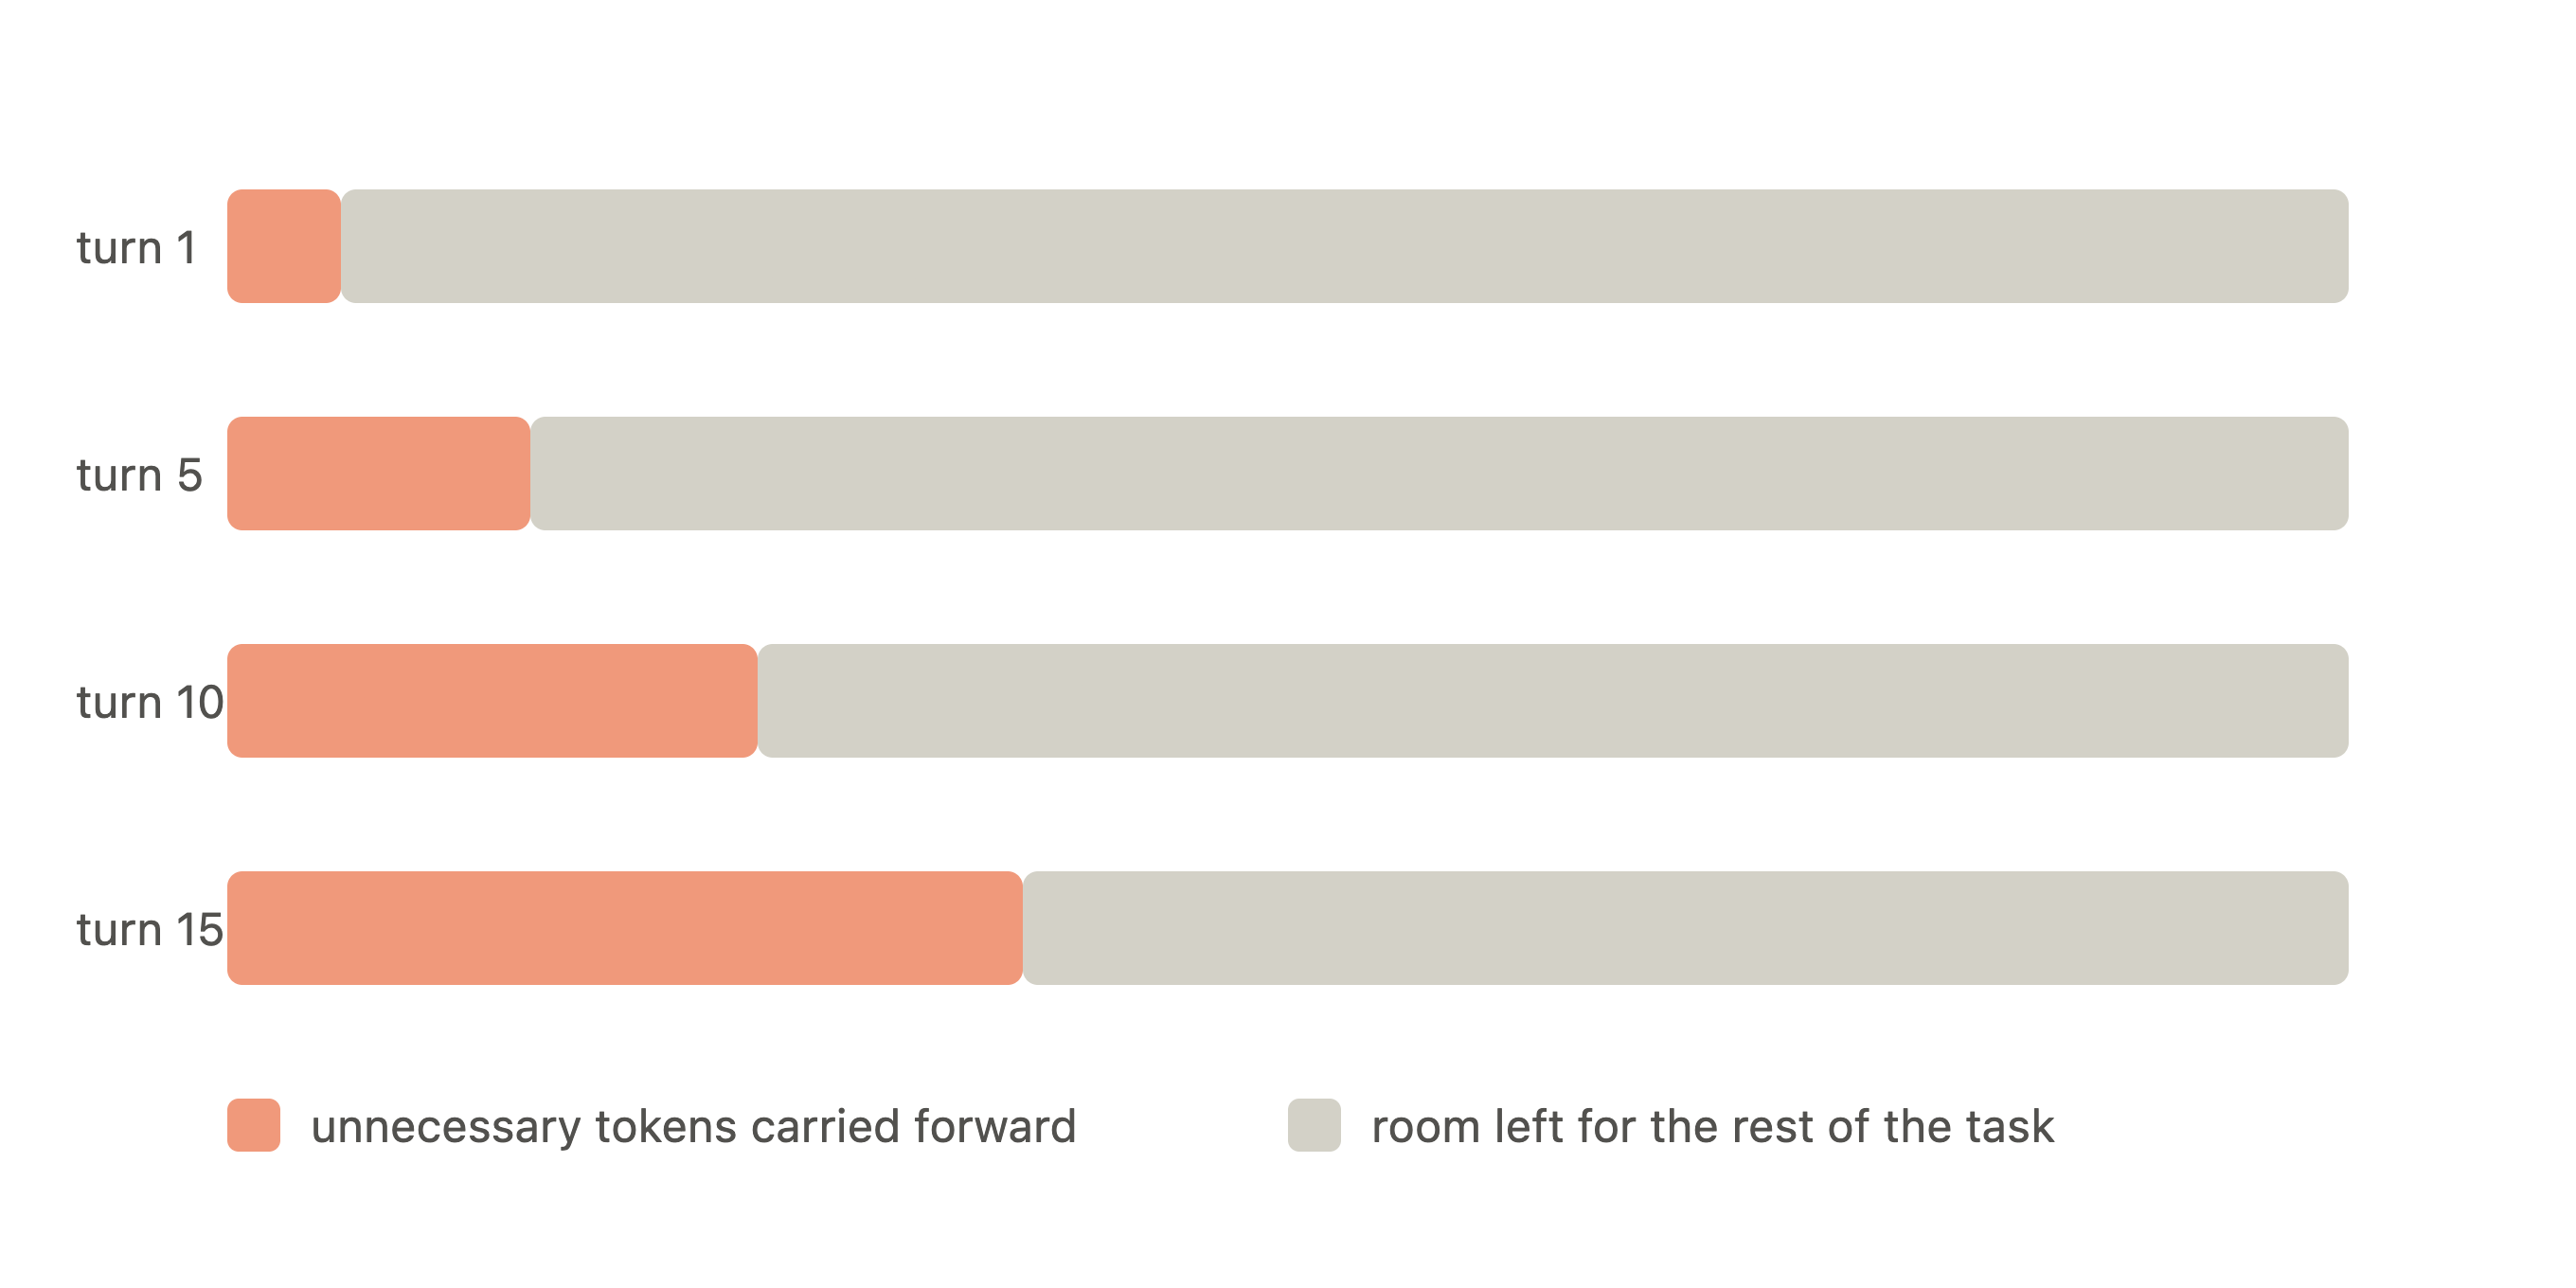
The transcript-polling incident kept bothering me for a reason that had nothing to do with token cost. A token bill is one-time, you pay it and it's over. What happened here was different. The raw transcript stayed in the orchestrator's context after the tool call completed, and every turn after that carried it forward, whether or not it was still useful.
That was the moment I realized I had been treating two very different kinds of cost as though they were the same. Tokens are spent once. Context shapes every decision that follows. I wasn't simply looking at token consumption anymore. I was looking at the quality of the orchestrator's working memory.
That realization was carrying two separate ideas, and I want to pull them apart rather than let them blur together. The first is what I just described. Pollution left in context taxes every later turn. The second is not about running out of space at all. The more that's sitting in context, competing for attention, the harder it gets for a model to pick out what matters right now, even with plenty of room still free. A bigger context window doesn't fix that. It just gives the noise more room to pile up before anyone notices.
Context windows are only going to get bigger, that's a given. What matters is not how much room there is, but how much of what's sitting in that room is worth the model's attention. That's the real problem subagents need to solve, if they're used right.
Seen this way, the orchestrator is the only part of the system that accumulates understanding across a long session. It remembers why a design decision was made, carries forward architectural constraints, and knows which trade-offs have already been discussed. The subagents don't, and that's by design. They are supposed to be disposable. Exploration, repeated file reads, failed approaches, and noisy intermediate reasoning are meant to stay in worker contexts and never make the trip back to the main thread.
Cognitive Locality Changes What Parallelism Is For
This reframes the duplicated-orientation problem, which wasn't really “two agents reading the same files.” It was two agents independently reconstructing the same mental model of the codebase, because the work had been partitioned by task rather than by the knowledge each task required. I've started calling that distinction cognitive locality: Tasks that need the same mental model should usually stay together. Splitting them just forces multiple agents to rebuild the same understanding from scratch.
Parallelism still matters here, it's just not the main point. Running four agents concurrently is useful, but ordinary. The real benefit is that they keep noisy intermediate reasoning out of the main thread and return only what it still needs. That's the isolation subagents are supposed to provide, and it only holds if the main thread respects it.
My working belief now: this is what subagents are actually for. Not that they save time, but that they let you offload reasoning the orchestrator doesn't need to hold onto, so it has less to carry and less competing for its attention. Get the isolation right, keep things local by cognitive locality, and subagents become the tool that protects the orchestrator's working memory, not just a cost you tolerate for parallelism. That's a belief, though, not a measurement. What I've actually measured is the other side of it, the cost of getting the isolation wrong.
Turning a Session into Standing Rules
My next move was the obvious one. Encode the lesson into CLAUDE.md, the standing instruction file every session loads.
It would have been easy to write a large corrective policy here, but every extra line in a standing instruction file is a cost paid again on every future session. So I compressed the fix into the smallest set of rules that addressed the failures I'd seen. Each one is really answering the same question. Does this piece of information, or this way the work is split, earn a place in the orchestrator's context?
- Prefer two to four agents in one wave. If the orchestrator wants five or more, it should first ask whether tasks sharing files or conventions ought to be merged.
- Do not poll background agents for status when the answer can be given from what is already known. Do not fetch a full transcript to answer a lightweight question.
- Do not allow repository-wide git operations inside concurrent agent prompts.
- Treat overlapping file ownership as a consolidation signal, not a cue to spawn more agents.
None of these tell the orchestrator exactly what to do in every case. Each one gives it something to check or ask itself before acting, not a script to run, and none of them is profound on its own. Their only real value is that they're all aimed at the same thing, keeping disposable reasoning disposable and keeping room in the orchestrator's context for what it needs later in the session.
The Next Mistake Would Have Been More Governance
A later session surfaced a different gap. I had started the orchestrator with explicit skills for the kind of work I wanted, coding guidance in one case, design guidance in another. I assumed that once a skill was active in the main thread, spawned subagents would follow it automatically. They don't. A subagent doesn't inherit skills active in the parent session unless the orchestrator passes them along explicitly.
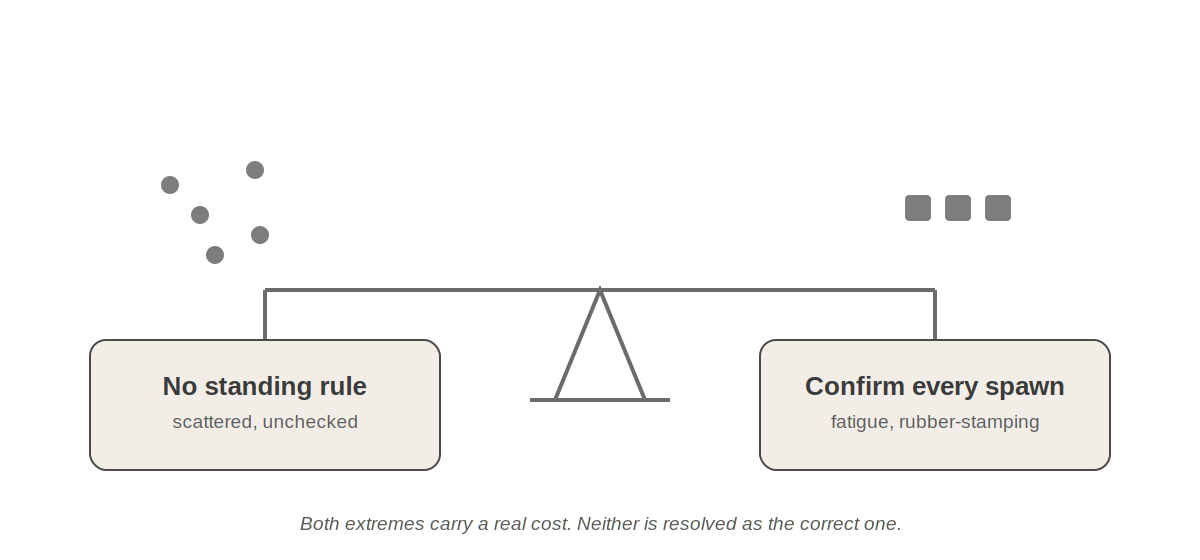
My first instinct was to add a confirm-before-spawn gate. The orchestrator would stop, list which agents it wants to launch and which skills each should load, and wait for my approval.
I'm glad I didn't keep that version. It solved the wrong problem. I didn't have evidence that bad spawn plans were slipping through for lack of a confirmation step. I'd discovered a missing fact about skill propagation, and that's a different kind of gap. A universal confirmation gate would have added a round-trip to every similar session, and before long I'd almost certainly have started approving those prompts on autopilot.
At that point, I realized I wasn't really improving governance. I was just adding another ritual.
And it still wouldn't have caught the real problem from before, the orchestrator polluting its own context.
The narrower fix held up better. Before spawning, the orchestrator states which active skills are relevant to each agent's task and points the subagent at the skill file to load, rather than pasting the whole skill inline. Confirmation is only required above the same batch-size threshold already in place, or when file ownership is ambiguous.
That left me with a heuristic I now use more than the rule itself: Before adding a line to a standing instruction file, ask whether a reasonably competent orchestrator would make the right decision once it knew the one missing fact.
If yes, the rule should just state the fact. If the fix starts specifying a decision procedure, such as approvals, checkpoints, mandatory steps, that's usually a sign I'm encoding process where a small clarification would have done the job.
I don't know yet whether that heuristic survives harder cases. For now it stops me from turning every interesting incident into a miniature bureaucracy.
Where This Leaves Me
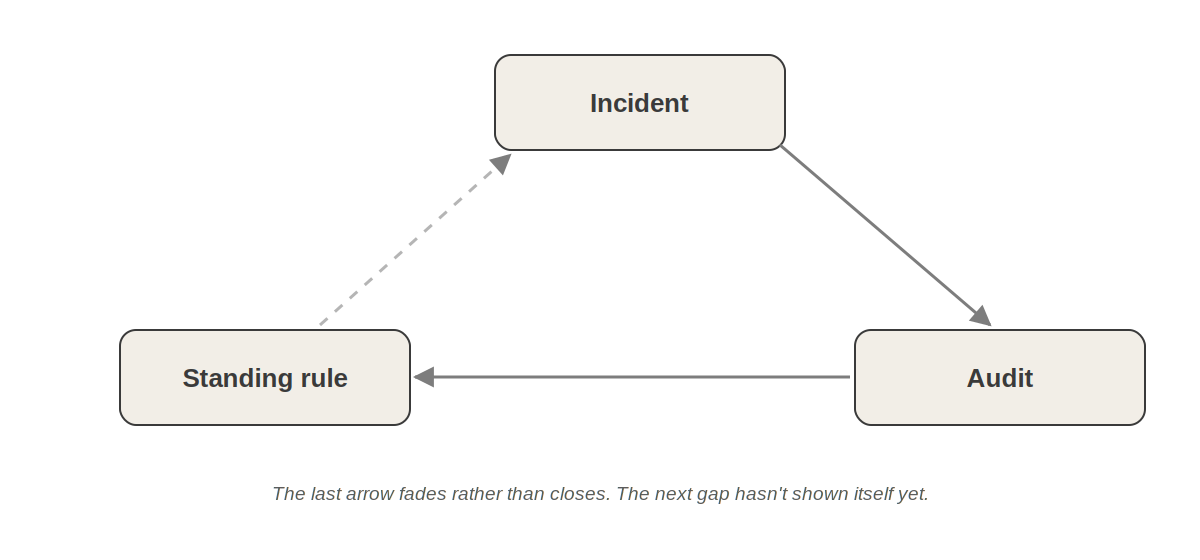
I don't have a settled view of how much governance is enough, and I don't think this piece earns one.
What I have instead is a small flywheel, with a human still firmly in the middle of it. A session exposes a gap. Someone has to notice that it felt wrong, stop the work long enough to inspect it, decide whether the problem is real or just noise, and judge what deserves to become a standing rule. The orchestrator can grade its own session and surface clues, as it did here, but it cannot make that judgment call itself. The choice of what to codify, what to leave alone, and what might be an overreaction is still mine. The next session then tells me whether that judgment improved the work or just created a different kind of waste.
The artifact of this round is the current version of my CLAUDE.md. It isn't a finished prescription. It's the state of the calibration after this iteration. The thresholds in it, two to four agents per wave, five as a consolidation signal, fit the work I was doing when I wrote them. I wouldn't present them as anything like universal constants, and I'd be suspicious of any orchestration write-up that did. They were also calibrated against Claude Sonnet 5, and I haven't tested how they hold up against others. A different model might reasonably need a different balance. A few more rules have accumulated in the file since. Treat this file as a sample, not a template, modify and optimize it for whatever model and workflow you're actually running. What matters isn't the specific file, it's the habit behind it: noticing a failure, asking what it actually cost, and writing the rule that would have caught it.
For years we optimized software systems around CPU, memory, and throughput. The first wave of LLM tooling taught us to watch tokens. This session made me suspect there's a third thing worth watching in long-running agent workflows: the quality of the orchestrator's own working memory, the one resource that, once polluted, keeps charging rent for the rest of the session. I don't think that's a settled law yet. It's a pattern that held up in the sessions I've looked at so far.
The tax I went looking for was never on the subagents. It was on the orchestrator, in what it chose to carry forward. That's the question I carry into every multi-agent design now: not how many agents to run, but what earns a place in the orchestrator's context.
The questions I'm left with are genuinely open:
- How do I measure this properly, instead of relying on the orchestrator's own account of its mistakes?
- When should a missing fact go into the instructions, and when does that turn into too much process?
- What's the next orchestration mistake I'm not seeing yet?
I expect I'll revise the file again. That feels less like a failure of foresight and more like the normal cost of working with a system opaque enough that doubt itself becomes part of the method.
Acknowledgments
The move to turn this incident into a standing CLAUDE.md rule owes something to Birgitta Böckeler's Harness Engineering, which names the loop I was running without having a word for it at the time. A feedforward guide (the CLAUDE.md rule) meets a feedback signal (the orchestrator's own self-critique, and my review of the session), with a human steering the update. That article names three kinds of harness: maintainability, architecture fitness, and behaviour. What this piece describes, using subagents deliberately to protect what the orchestrator carries forward, belongs to a fourth, the orchestration process itself.
Thanks to Martin Fowler for his guidance and feedback throughout, which pushed this piece toward clearer thinking and articulation.
ChatGPT and Claude served as pair editors on this piece, helping with grammar, sentence crafting, and paragraph structure wherever it was needed.
Significant Revisions
28 July 2026: