Towards Automating Eval Engineering
Today we’re releasing our Eval Engineering Skill, a skill that helps coding agents build evals using context from a repository and agent tra...
📝 摘要
LangChain 发布了 Eval Engineering Skill,一种帮助 coding agent 利用代码仓库上下文和 agent traces 自动构建 eval(评测)的技能。该 skill 会扫描仓库映射 agent 的能力面(prompts、models、tools、skills、hooks),并可读取 langsmith-cli 采集的 traces 来挖掘工具的实际调用契约,进而在可控环境中复现生产行为;最终通过采访式交互让用户对提议的 eval 方向逐一反馈与迭代批准,产出 Harbor 格式的可执行评测。文章以文档问答 agent chat-langchain 为案例,强调 eval 设计本质是迭代的——通过同时观察 agent trajectory 与 verifier trajectory 来发现 reward hacking(过度引用、谎报动作、利用暴露答案、满足代理指标等捷径),并据此反复修订 task、environment 与 verifier。
核心概念: 将持续学习视为持续数据挖掘问题——挖掘 traces 中的失败模式并将其转化为 eval,eval 作为 agent 的"训练数据"为 harness 工程(改 prompt/tools 或 fine-tune)提供固定改进靶标。
关键技术栈 / 关键要点:
- Eval Engineering Skill — 读取仓库 + traces 映射 agent 能力面,采访用户迭代生成 eval,而非一次性生成
- Harbor 格式 — 评测由 Instruction + Environment(Dockerfile)+ Verifier 三部分组成,容器化使环境稳定、可并行对比不同 model/prompt/tool 配置
- Iterative Eval Design — 最佳 eval 来自用户反馈循环;首版 verifier 很少是最终版,需双向检查 agent 与 verifier 的 trajectory
- Reward Hacking 防御 — 观察 trace 揭示 agent 走捷径的来源(overciting、虚假动作、答案泄漏、代理指标),据此修订评测
- Continual Learning Loop — mine traces → identify failure → build eval → improve agent → rerun,容器化可复现环境是信号可靠性的关键
关键结论 / 实践建议: 评测是 agent 的训练数据,应将 continual learning 当作数据挖掘流水线来运营;容器化、可复现的 eval 环境让团队能快速实验并直接对比不同 agent 配置,而不依赖变动中的生产系统。
Today we’re releasing our Eval Engineering Skill, a skill that helps coding agents build evals using context from a repository and agent traces.
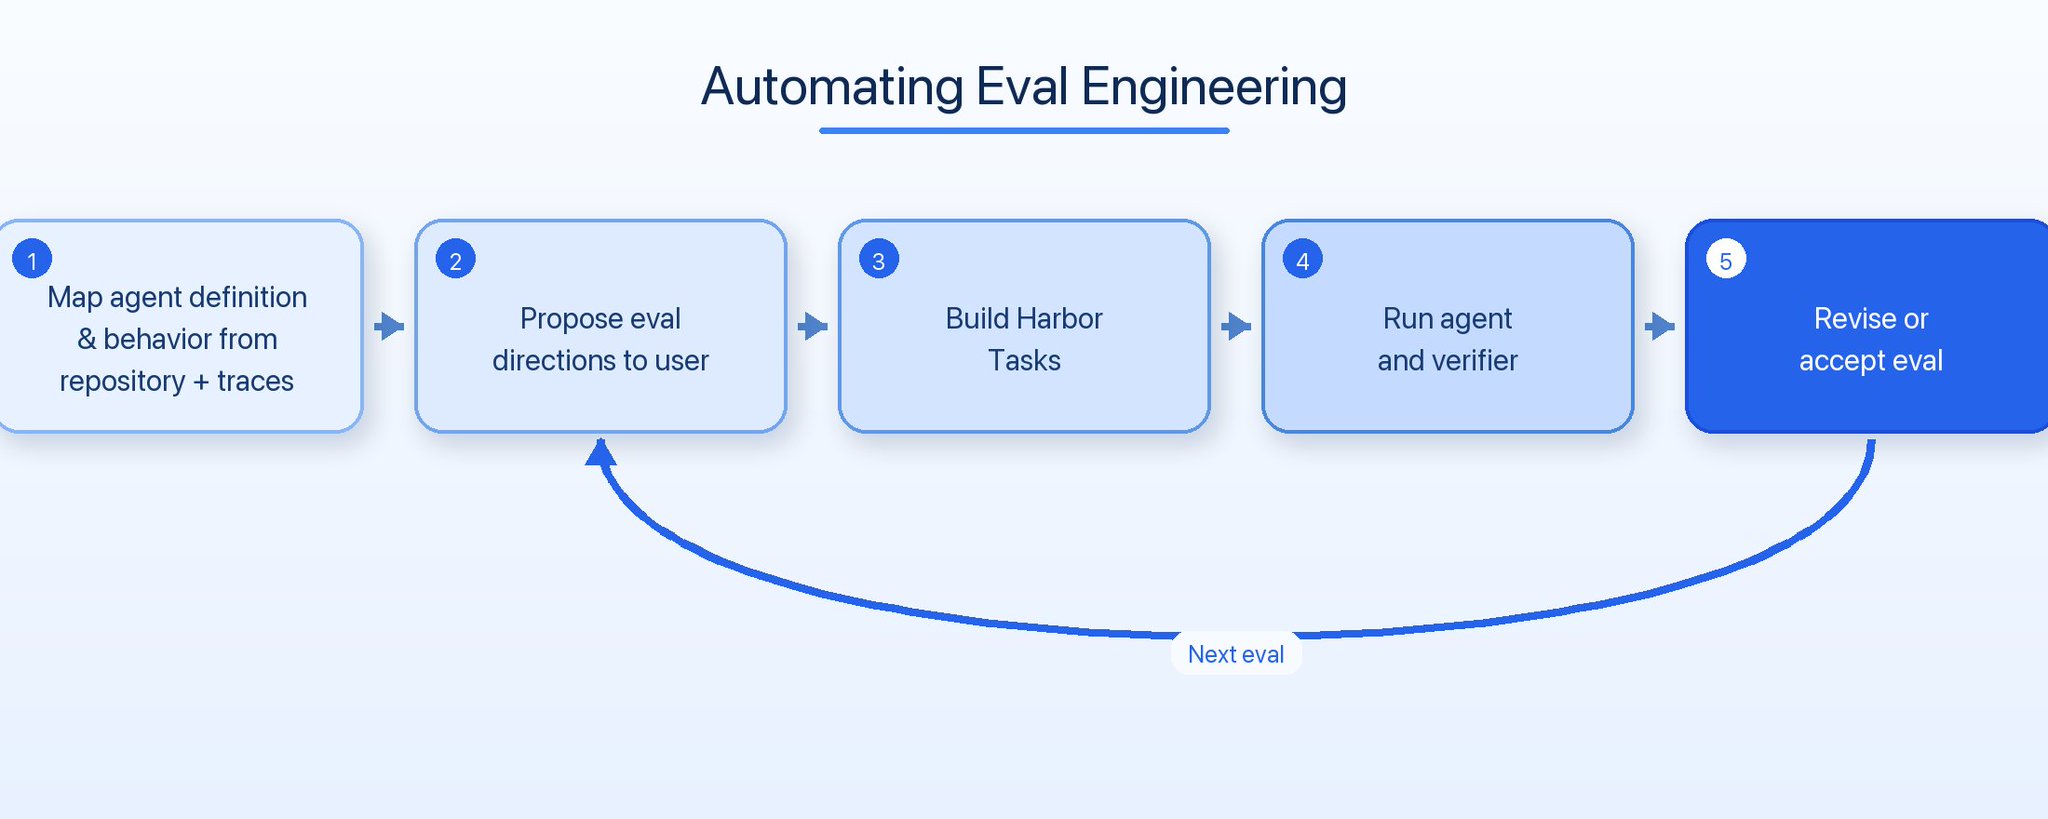
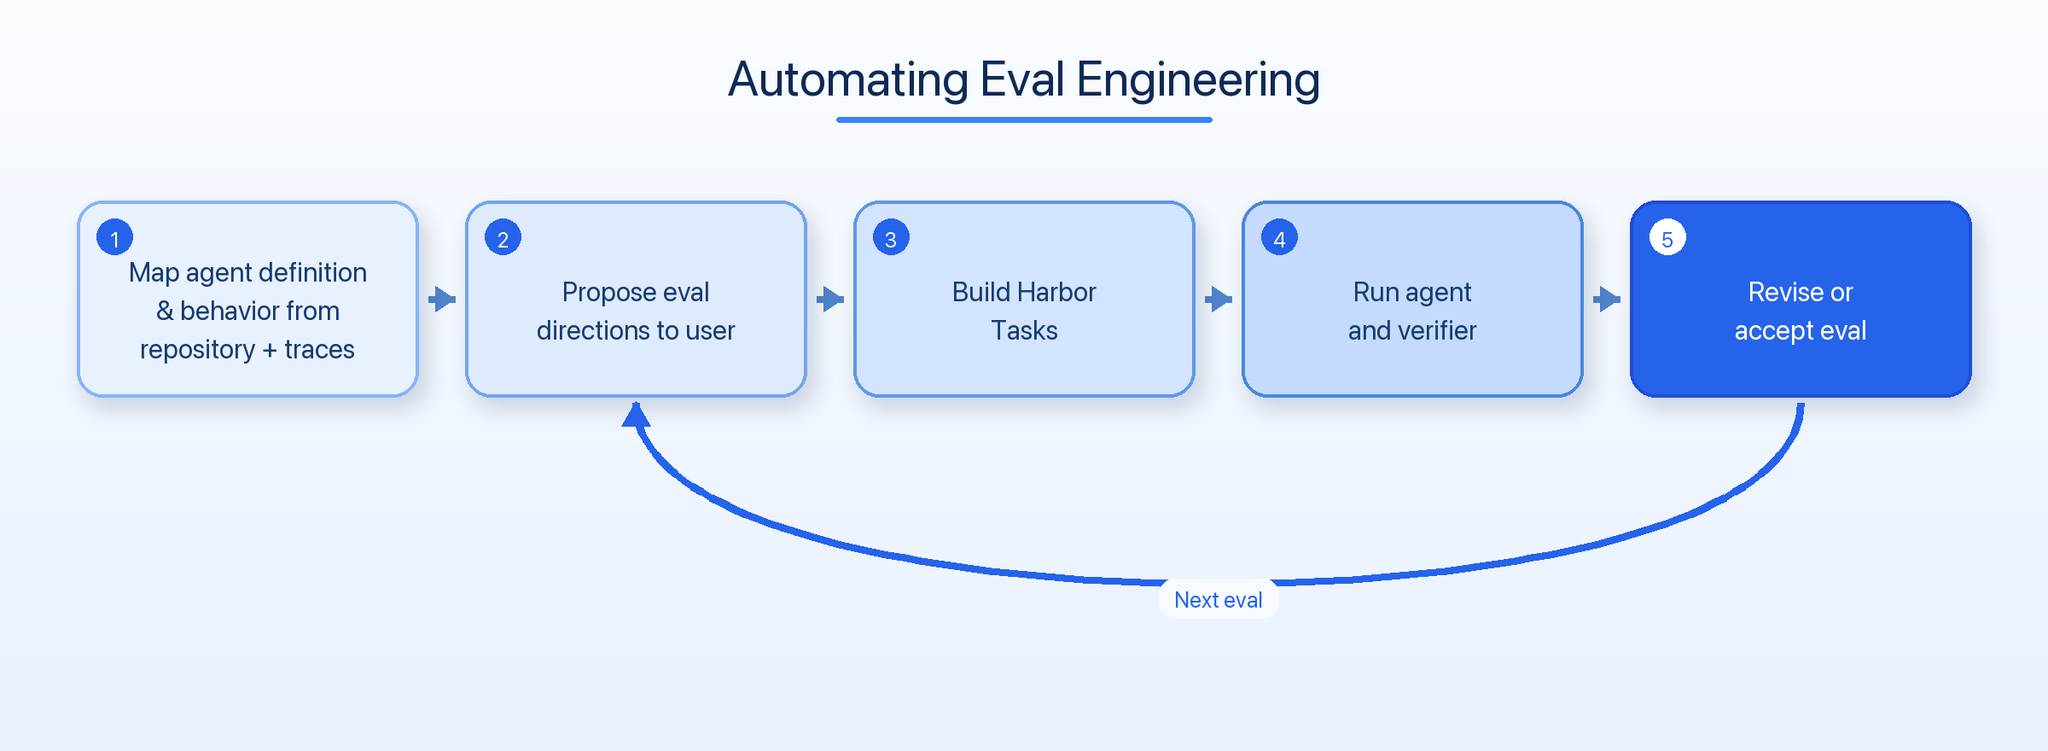
The skill inspects how an agent is structured, mines patterns from traces if available, and proposes abilities to test.
The skill is designed to interview the user who can give feedback on proposals and iteratively approve each eval. The end product is a set of executable evals in Harbor format.
Building the Environment & Task
The skill first reads the repository and maps the agent surface including prompts, models, tools, skills, hooks, etc. It also identifies the data and services that back those behaviors such such as API calls.
Users can also point the agent to traces which can be retrieved using tools like the langsmith-cli. Traces show how tools behave in practice such as their arguments, results, and errors. These observed contracts help the skill reproduce relevant production behavior in a controlled environment.
Crawling the repo and traces gives the agent knowledge of a which abilities are important for the agent as it proposes eval tasks. We found that interviewing the user, leads to much better eval acceptance than one-shot generation. The user chooses from the proposed eval directions, and gives guidance on questions such as which tools & dependencies should run live or need to be simulated. For example, tool calls that incur costs or require writes to production can be simulated instead of being run on every eval invocation.
We tested this flow on our documentation Q&A agent, chat-langchain. For this agent, the environment required a data corpus exposed through agent search tools modeled on the production agent. The tasks included realistic documentation question pulled from real traces and a verifier that checked the answer using a golden answer string and cited documents.
Eval Design is iterative
We found that while agents are sometimes able to one-shot evals, the best evals came from users providing feedback and specifying which capabilities were worth measuring in agents. Coding agents & skills provide a natural interface where domain knowledge on how to build a good eval are encoded and users can iterate over them over time.
For example, we found that when building verifiers, the first verifier was rarely the final one. A useful way to improve it was to run the eval and inspect both sides of the result:
- the agent trajectory, including its messages, tool calls, and actions.
- the verifier trajectory, evidence, reasoning, and final score.
This helped reveal if the task or verifier design was measuring what we cared about or if it could be reward hacked where agents could take shortcuts. These shortcuts could include overciting irrelevant sources to receive full credit on the eval, claim an action it never took, exploit exposed answer material, or satisfy a proxy without completing the task. Observing the traces for how agents solve problems often reveal the source of these failures. The task, environment, and verifier can then be revised and run again.
Evals are in Harbor format
The skill builds evals as Harbor tasks:
- An Instruction: the message given to the agent at start describing the task
- An environment: given as a Dockerfile containing the setup for the task such as what tools to install or what data to populate in the filesystem
- A verifier that scores whether the agent completed the task correctly.
The skill builds these components together as a Harbor task:
evals/<task-id>/
├── task.toml
├── instruction.md
├── environment/
└── tests/
Harbor runs the agent in the environment and records its trajectory, artifacts, reward, and errors. The same eval can then run against different models, prompts, tools, and agent versions.
Why this matters
Continual learning can be thought of as a continuous data mining problem where production data is used to build evals that improve agents over time. Teams mine traces to find recurring user requests, errors, failed tool calls, and incorrect state changes. which become evals so the same behavior can be measured and prevented in the future.
Evals are training data for agents. Teams can fit agent behavior to them through harness engineering such as changing prompts & tools or fine-tuning. The eval provides a fixed target for deciding whether those changes improved the intended capability.
Containerized evals make this process faster. The task and environment remain stable while the agent configuration changes, so builders can swap models, tools, prompts, or complete agent versions and compare results directly. Multiple configurations can run in parallel.
Reproducible environments are critical to that signal. When an eval mirrors the relevant tools, data, permissions, state, and failure modes from production, builders get a stable testbed that is still representative of how the agent operates. They can experiment quickly without relying on changing production systems or writing to production state.
The resulting loop is:
mine traces -> identify a failure -> build an eval -> improve the agent -> rerun
Try it today
The Eval Engineering Skill is available in the langchain-ai/langchain-skills repository.
Install the skill in Codex or Claude Code, open the repository containing the agent you want to evaluate, point to agent to a set of traces if available, and start with a simple prompt:
We’re looking forward to expanding this skill and building tooling to make it easier to automatically build evals and fit agents to them autonomously.