Advanced Observability for Production Systems
From SLIs to LLM monitoring: 9 practices that separate mature teams from dashboard collectorsMost teams have dashboards. Few have observabil...
📝 摘要
本文系统性地介绍了生产环境可观测性的 9 个高级实践,从基础的 SLI/SLO/SLA 与 Error Budget 体系,到可观测性的成本管控、安全与访问控制、开发者自助式可观测能力,再到 AI 驱动的异常检测与 LLM 应用专属监控。文章强调大多数团队停留在"有 Dashboard"的阶段,真正成熟的可观测性需要从意图出发——明确测什么、成本多少、谁负责、告警触发后做什么。
核心概念: 可观测性成熟度本质上是文化问题而非工具问题,需要在 SLO 驱动、成本治理、团队所有权和持续改进之间建立闭环。
关键技术栈 / 关键要点:
- SLI/SLO/SLA 与 Error Budget — 从可度量信号出发定义目标,用 Error Budget 驱动发布门控、回滚和可靠性冲刺
- 成本管控 — 通过采样策略(head/tail)、日志级别规范、存储分层(hot/warm/cold)和基数封顶控制遥测开销
- 安全与 PII 防护 — 在 Collector 层过滤 PII、传输/存储加密、RBAC 分域访问,定期审计
- 开发者自助 — 从中心化 SRE 演进到平台化自助,提升 MTTR 和工程团队 ownership
- AI/LLM 可观测性 — LLM 应用需要 prompt 版本、token 用量、幻觉指标、agent trace 等全新信号体系
- 反模式警示 — 12 个常见反模式(Dashboard 泛滥、虚荣指标、无信号 Owner 等)导致成本失控和信任下降
- OTLP 管线设计 — 将插桩与后端解耦,以 OpenTelemetry Protocol 作为统一信号传输协议
关键结论 / 实践建议: 先定义 SLO 再加 Dashboard,在构建阶段就插桩而非事后补救;可观测性成熟度的瓶颈在于治理和文化,而非工具选型。
From SLIs to LLM monitoring: 9 practices that separate mature teams from dashboard collectors
Most teams have dashboards. Few have observability. The difference is intent knowing what to measure, what it costs, who owns it, and what happens when an alert fires. This post (with the visual guide attached) covers the full picture.
1. SLI, SLO, SLA & Error Budgets — Start Here
- SLI = measurable signal of service behavior (availability, latency, error rate, freshness)
- SLO = target on that SLI (e.g., 99.9% availability)
- SLA = external commitment to customers — breach has consequences
- Error Budget = 100% minus SLO (0.1% ≈ ~43 min/month)
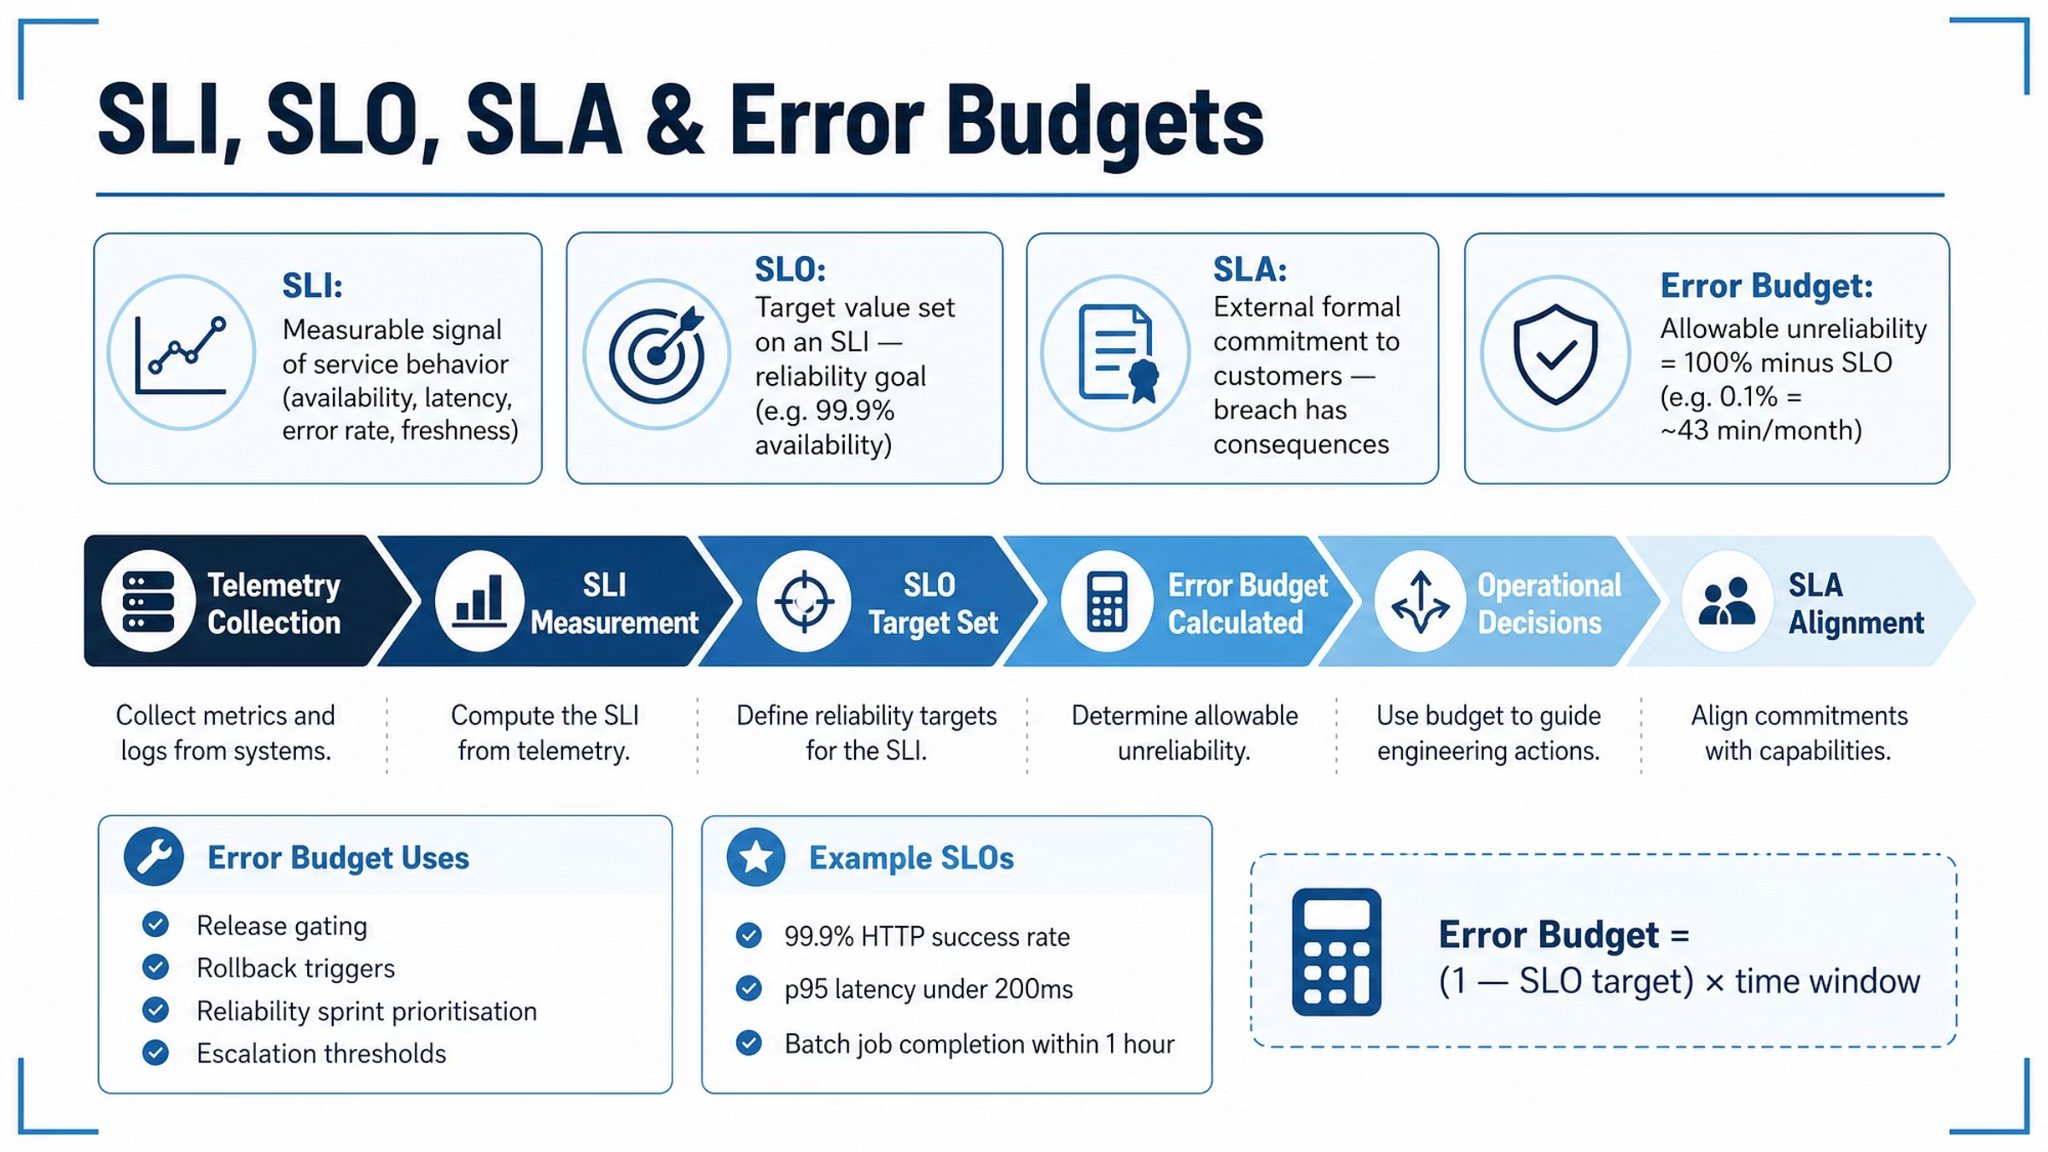
The flow: collect telemetry → measure SLI → set SLO → calculate error budget → use it to drive release gating, rollback triggers, reliability sprints, and escalation thresholds.
Error Budget = (1 − SLO target) × time window
2. Observability Cost Management — Telemetry Isn’t Free
Cost drivers: ingestion volume, storage retention, indexing, query execution, cardinality, and duplication. The biggest hotspots: noisy debug logs, always-on full tracing, and high-cardinality labels.
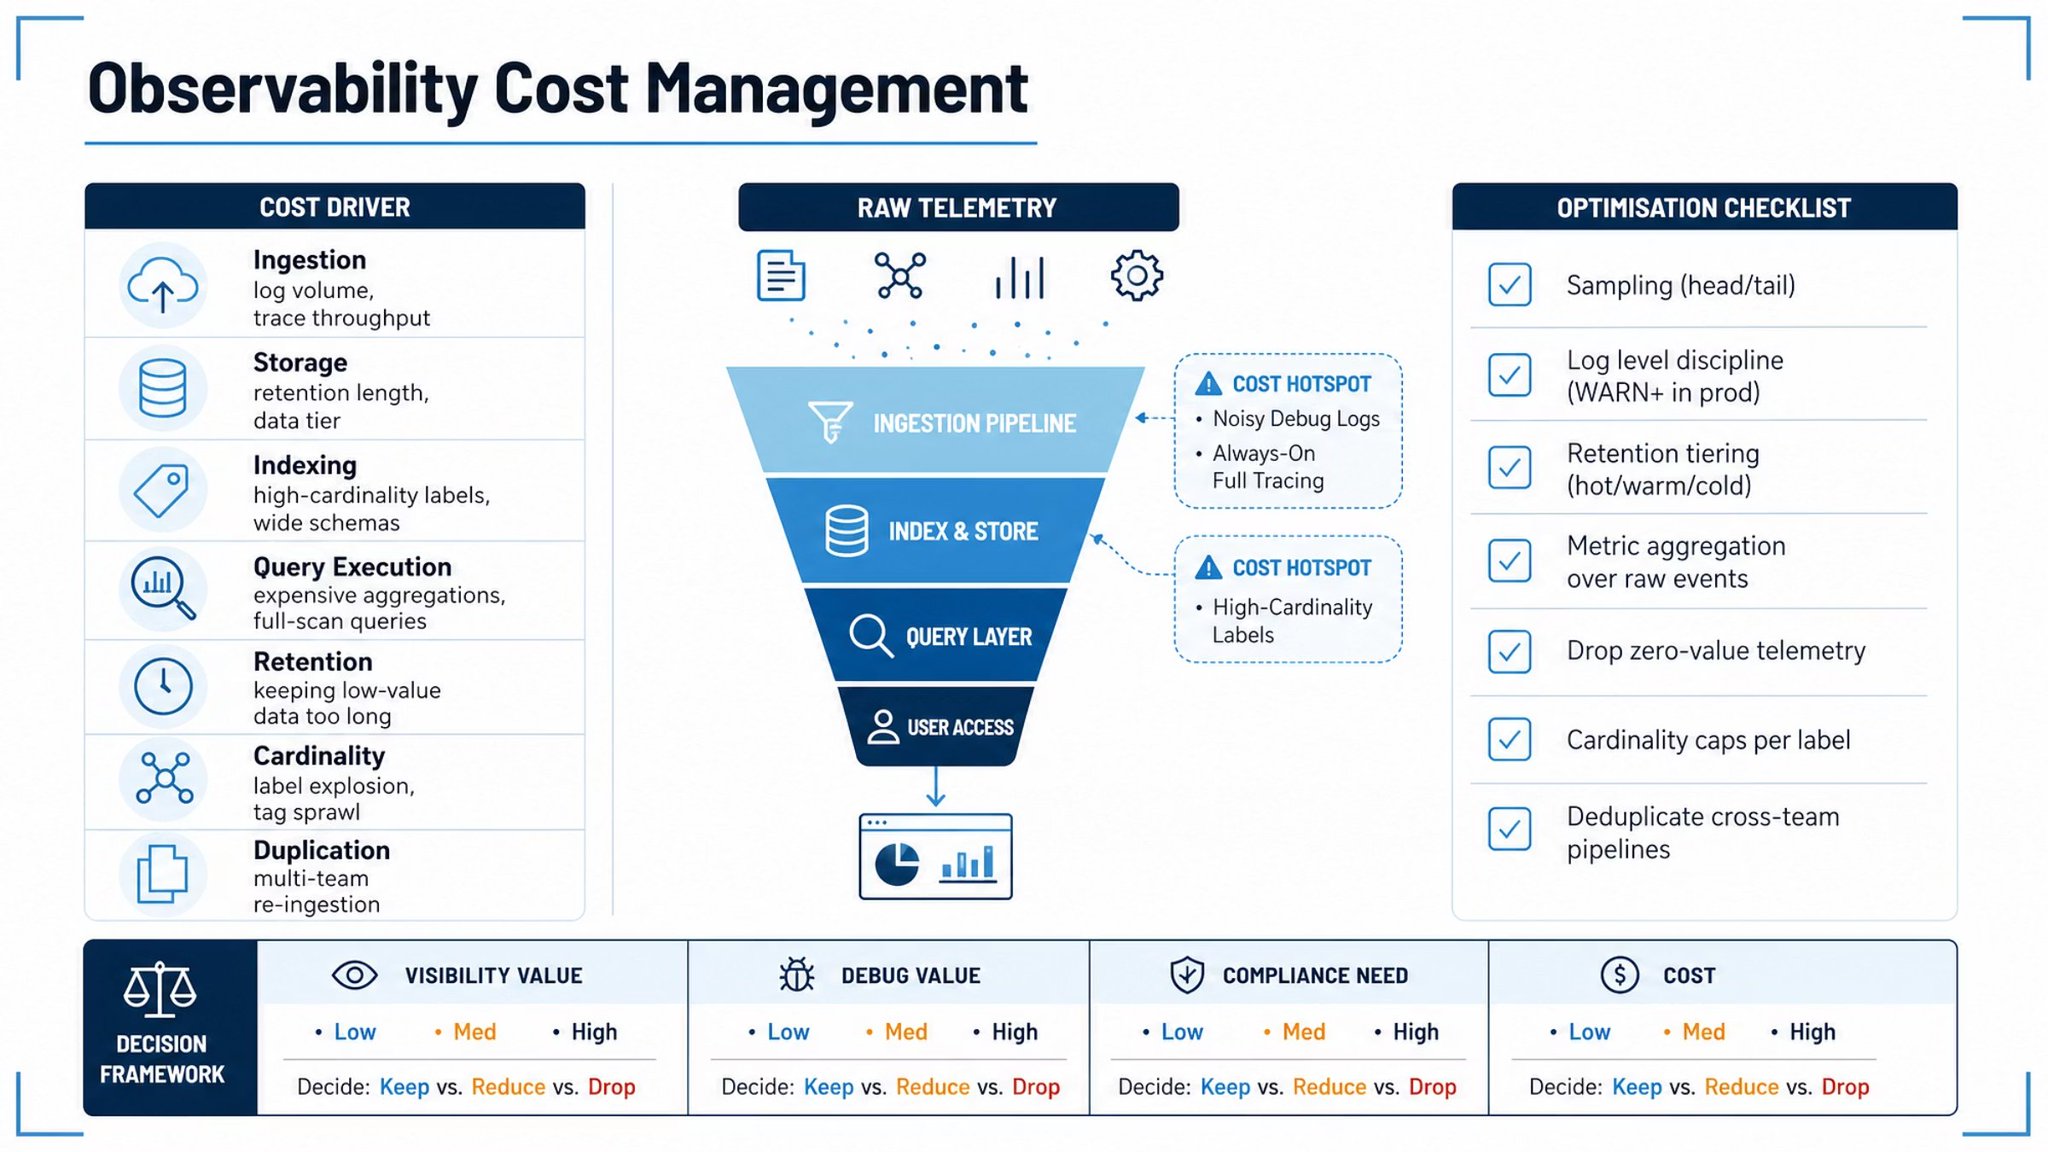
The optimisation checklist
- Sampling (head/tail)
- Log level discipline (WARN+ in prod)
- Retention tiering (hot/warm/cold)
- Metric aggregation over raw events
- Drop zero-value telemetry, cap cardinality, deduplicate cross-team pipelines
For every signal, decide Keep vs. Reduce vs. Drop based on visibility value, debug value, compliance need, and cost.
3. Security & Access Control — Your Logs Contain PII
Telemetry leaks customer IDs, auth tokens, internal topology, payload fragments, and IPs. Secure every layer: encrypt in transit, filter PII at the collector, encrypt at rest, enforce RBAC and team-scoped views, and audit all access.
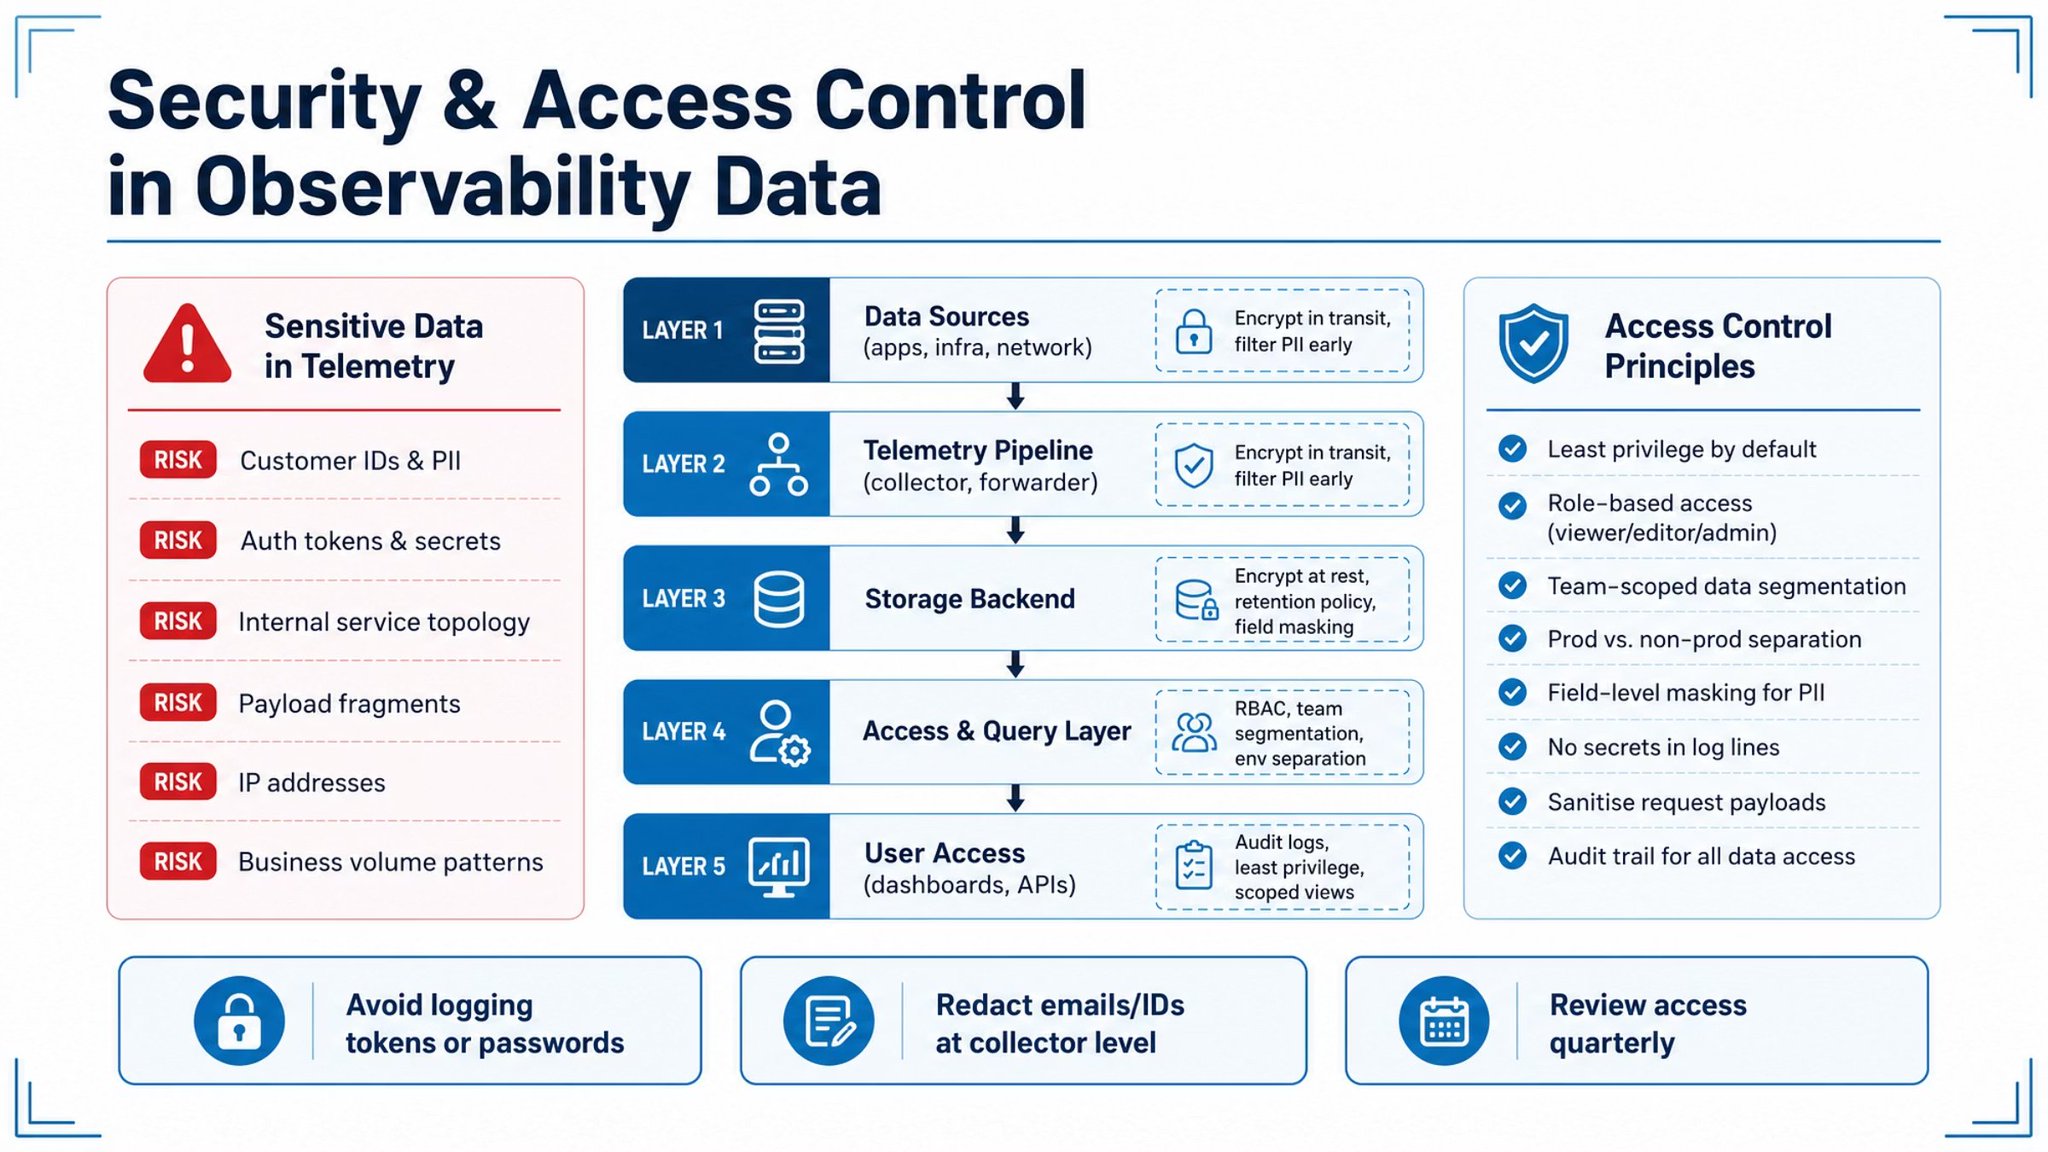
Three habits: never log tokens/passwords, redact emails/IDs at collector level, review access quarterly.
4. Developer Self-Service Observability
Maturity runs from “ops gate-keeps everything” to fully self-service: golden templates, auto-instrumentation, internal portal. Good self-service means devs can deploy, see auto-populated dashboards, get the alert, and investigate directly — no SRE ticket needed.
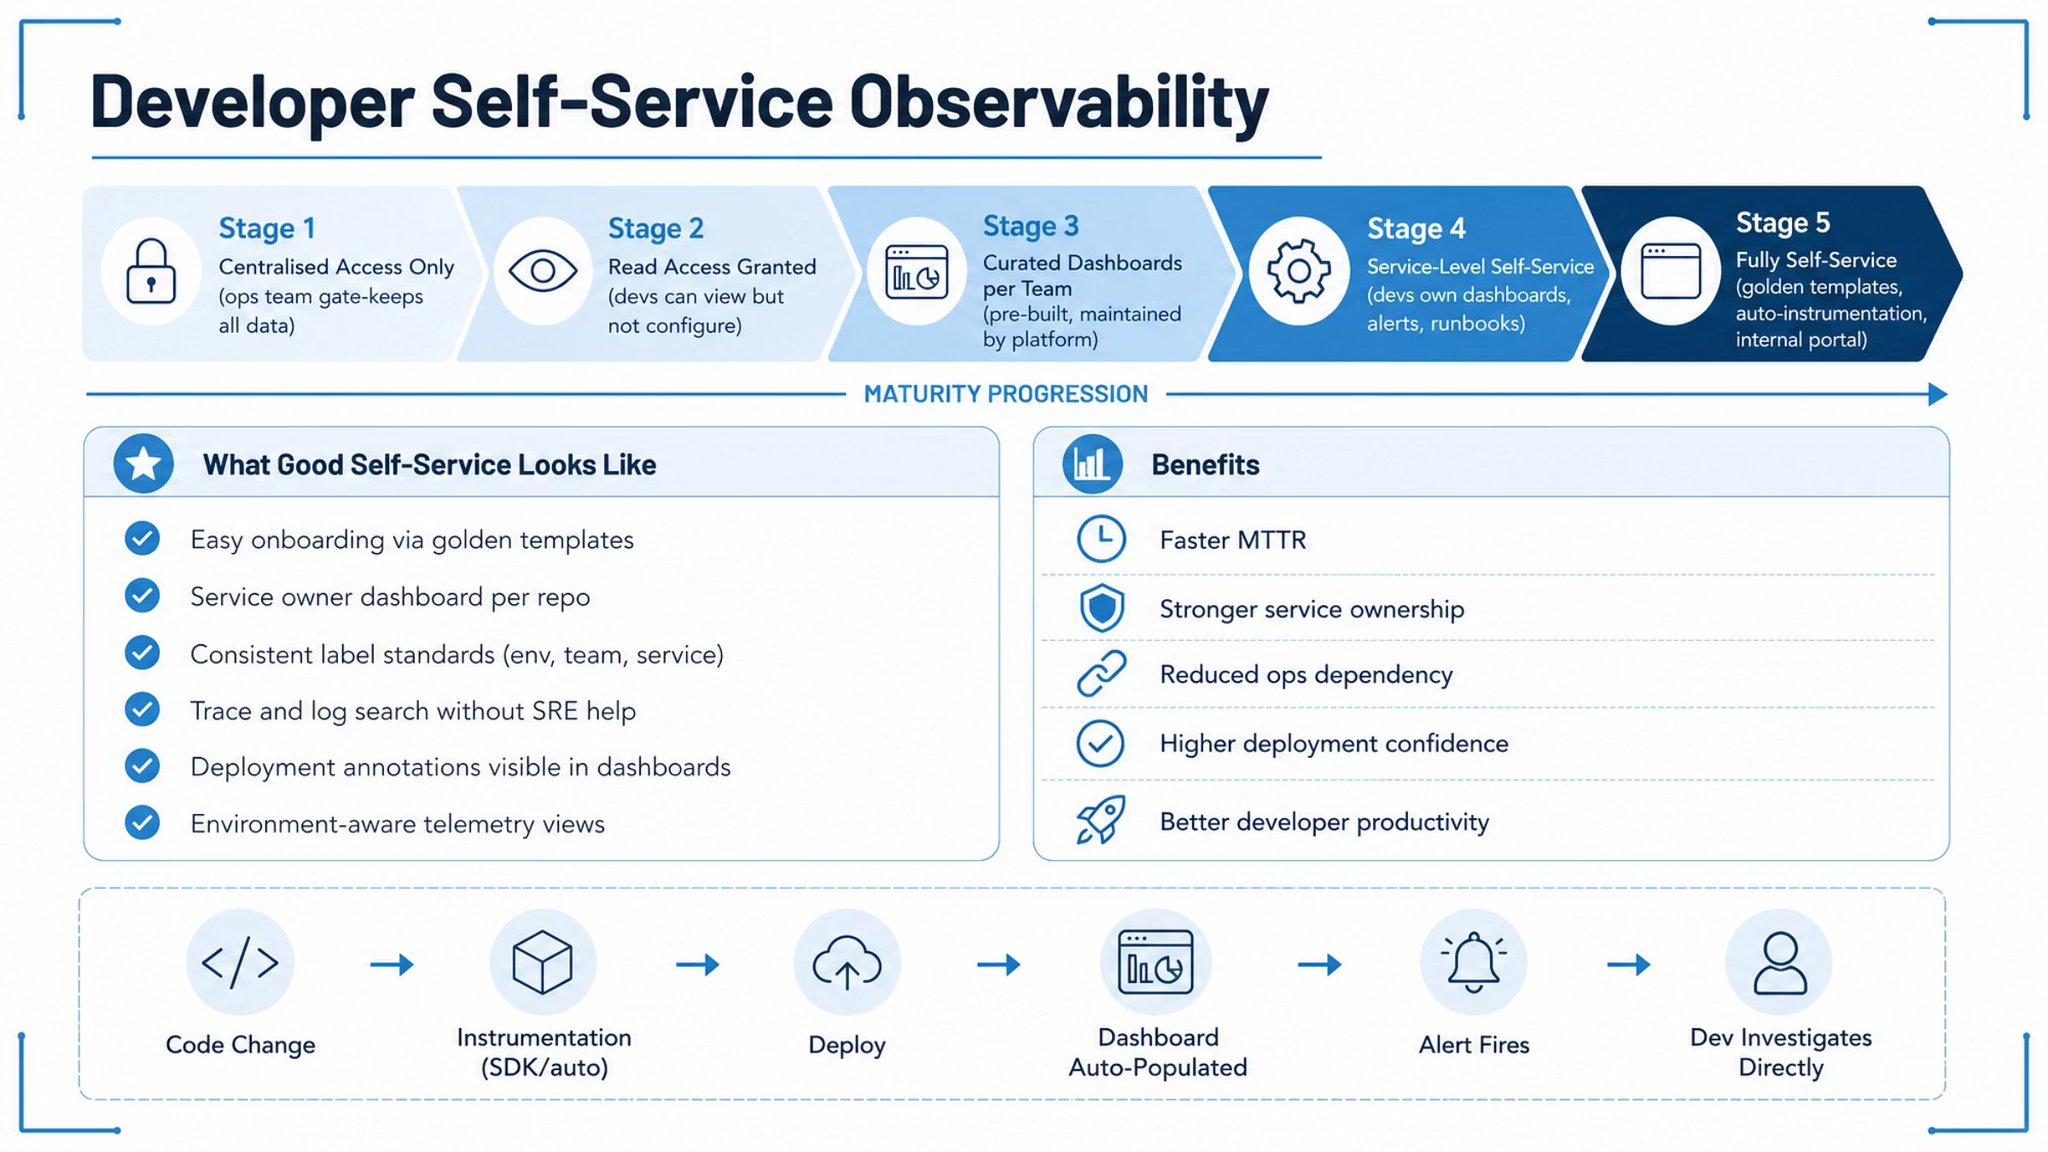
Result: faster MTTR, stronger ownership, less ops dependency.
5. AI for Observability & Anomaly Detection
AI shines at anomaly detection, log clustering, alert priority scoring, incident summarisation, change correlation, and root-cause suggestions. But know the limits false positives, opaque decisions, training drift, and overreliance risk.
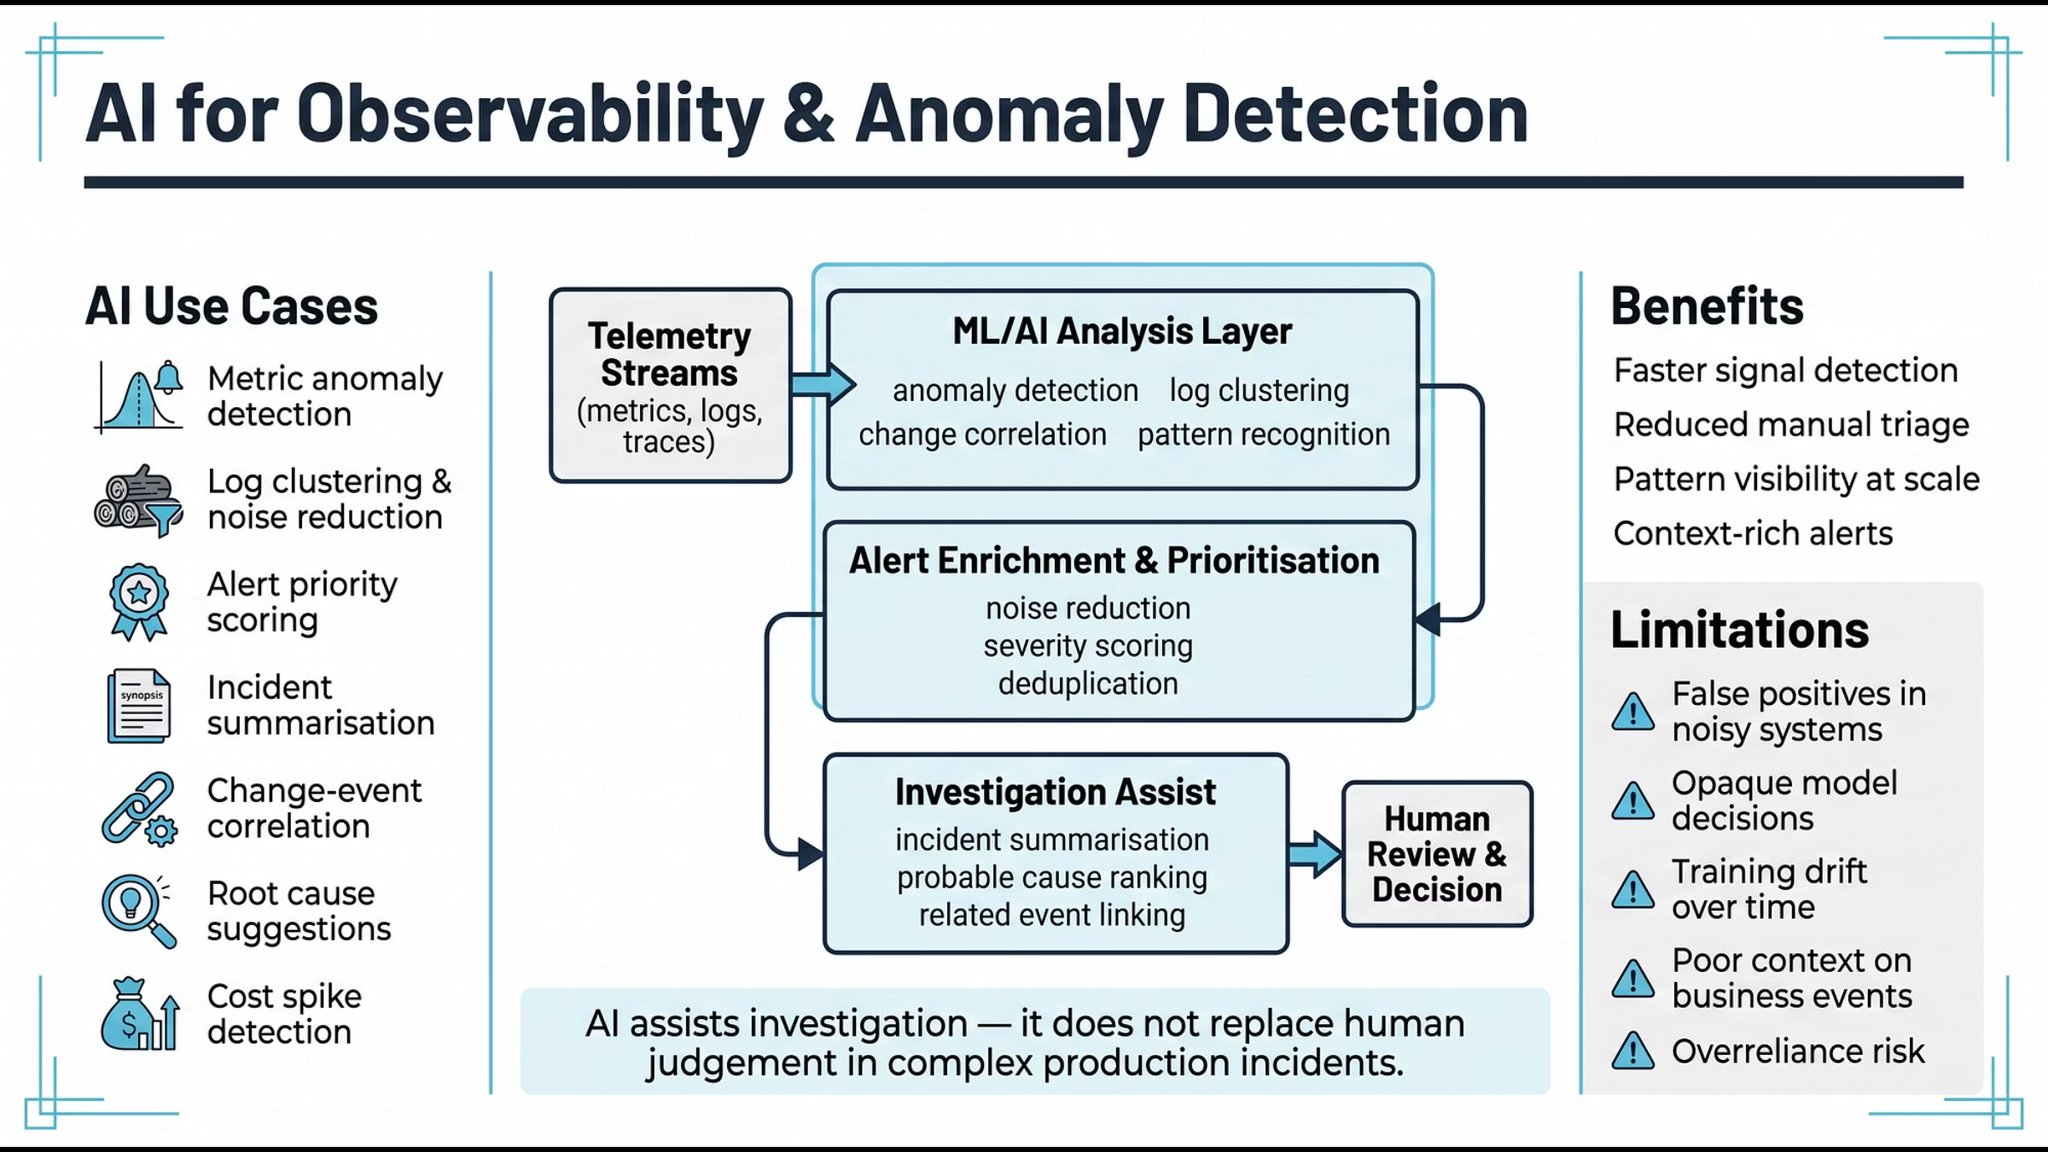
AI assists investigation — it does not replace human judgement in complex production incidents.
6. Observability Anti-Patterns That Cost You
The twelve killers: collect everything, dashboard sprawl, vanity metrics, no signal ownership, weak instrumentation, poor label discipline, no trace correlation, logging sensitive data, noisy alerts, single-signal reliance, no post-incident learning, and treating tooling as observability.
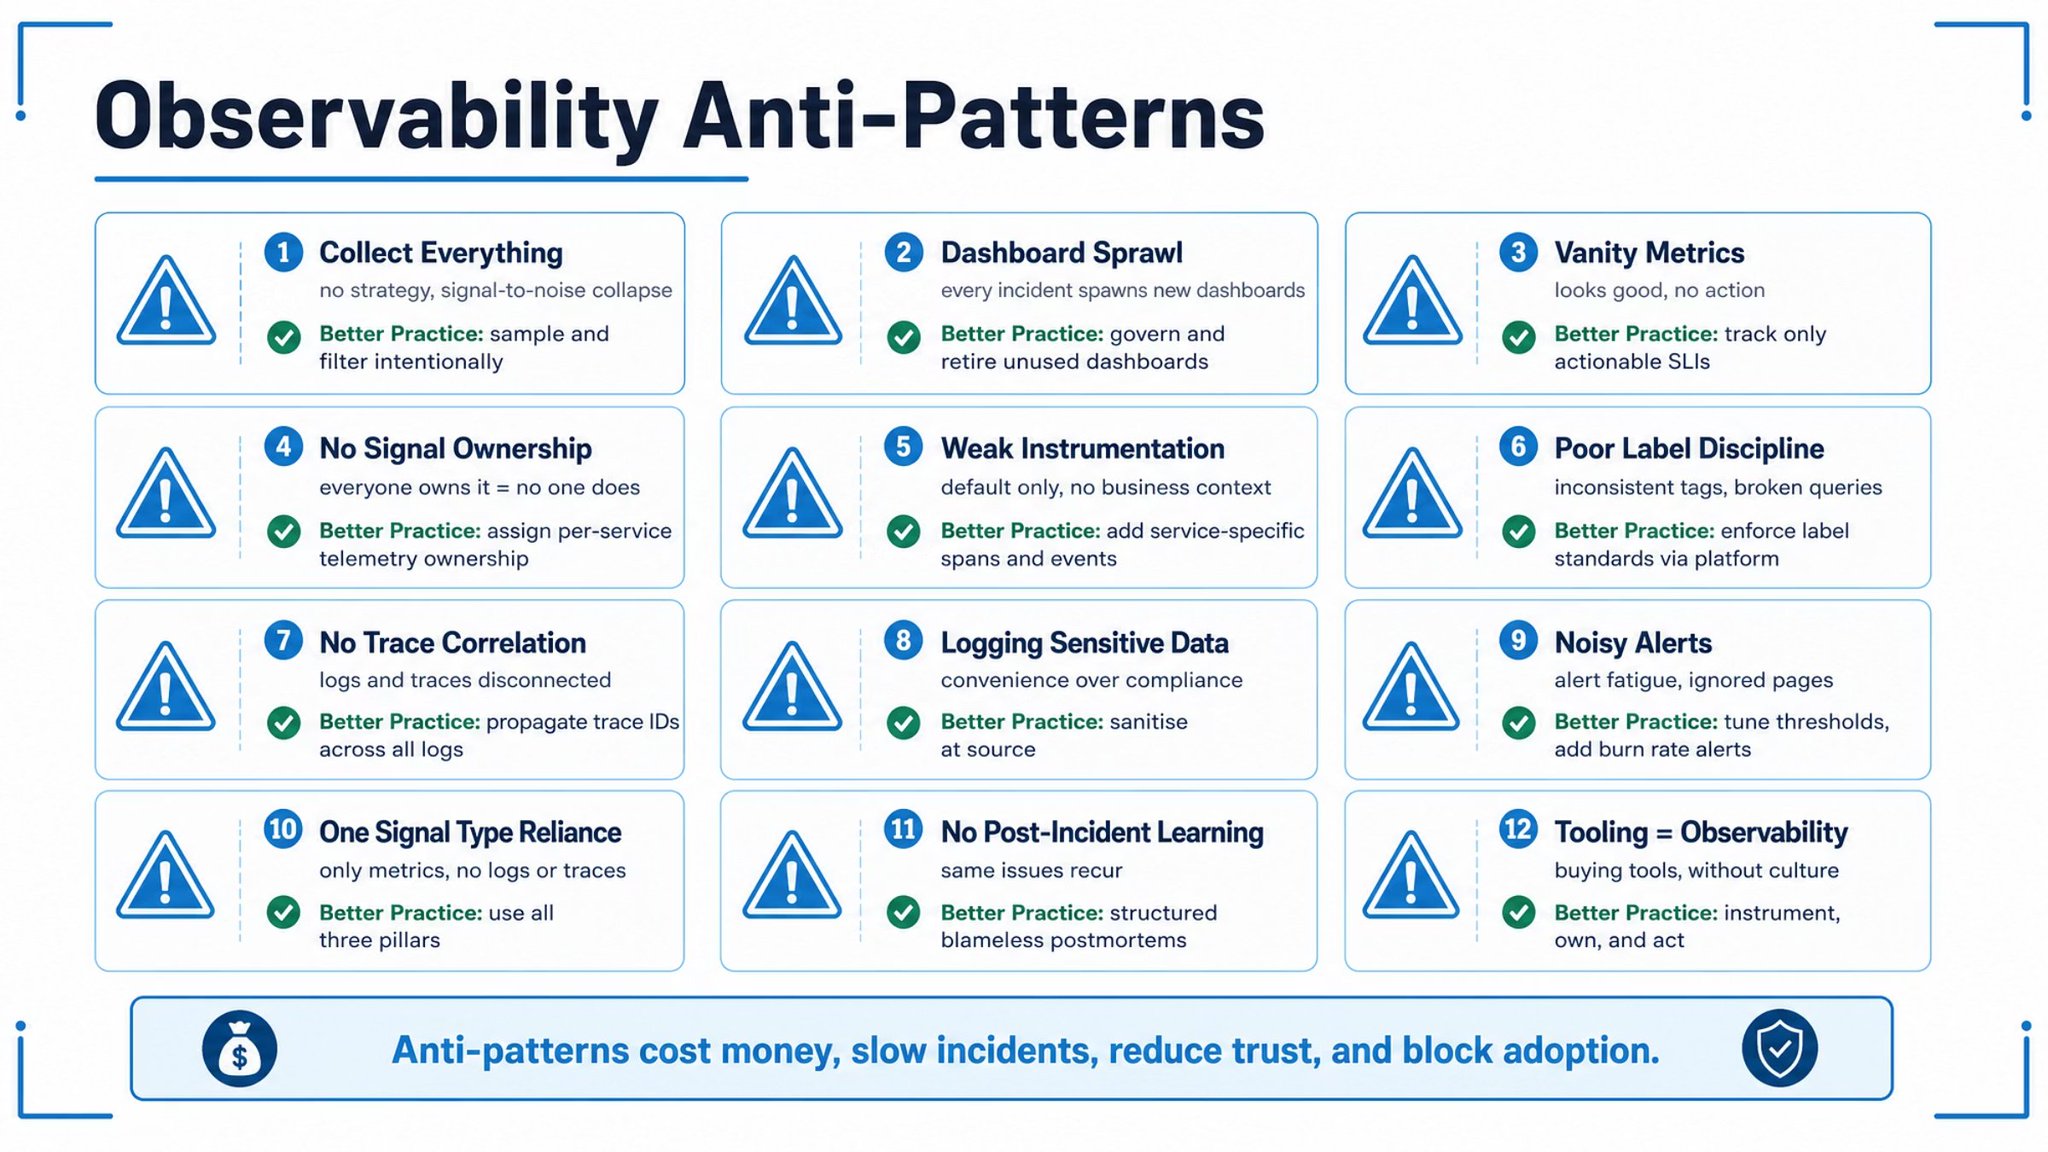
Anti-patterns cost money, slow incidents, reduce trust, and block adoption.
7. Team Ownership & Culture
Four models: centralised SRE, embedded ownership, platform-enabled self-service, and hybrid. Whatever the model, the reinforcement loop matters: devs own signals → better telemetry → faster triage → postmortem learning → better instrumentation.
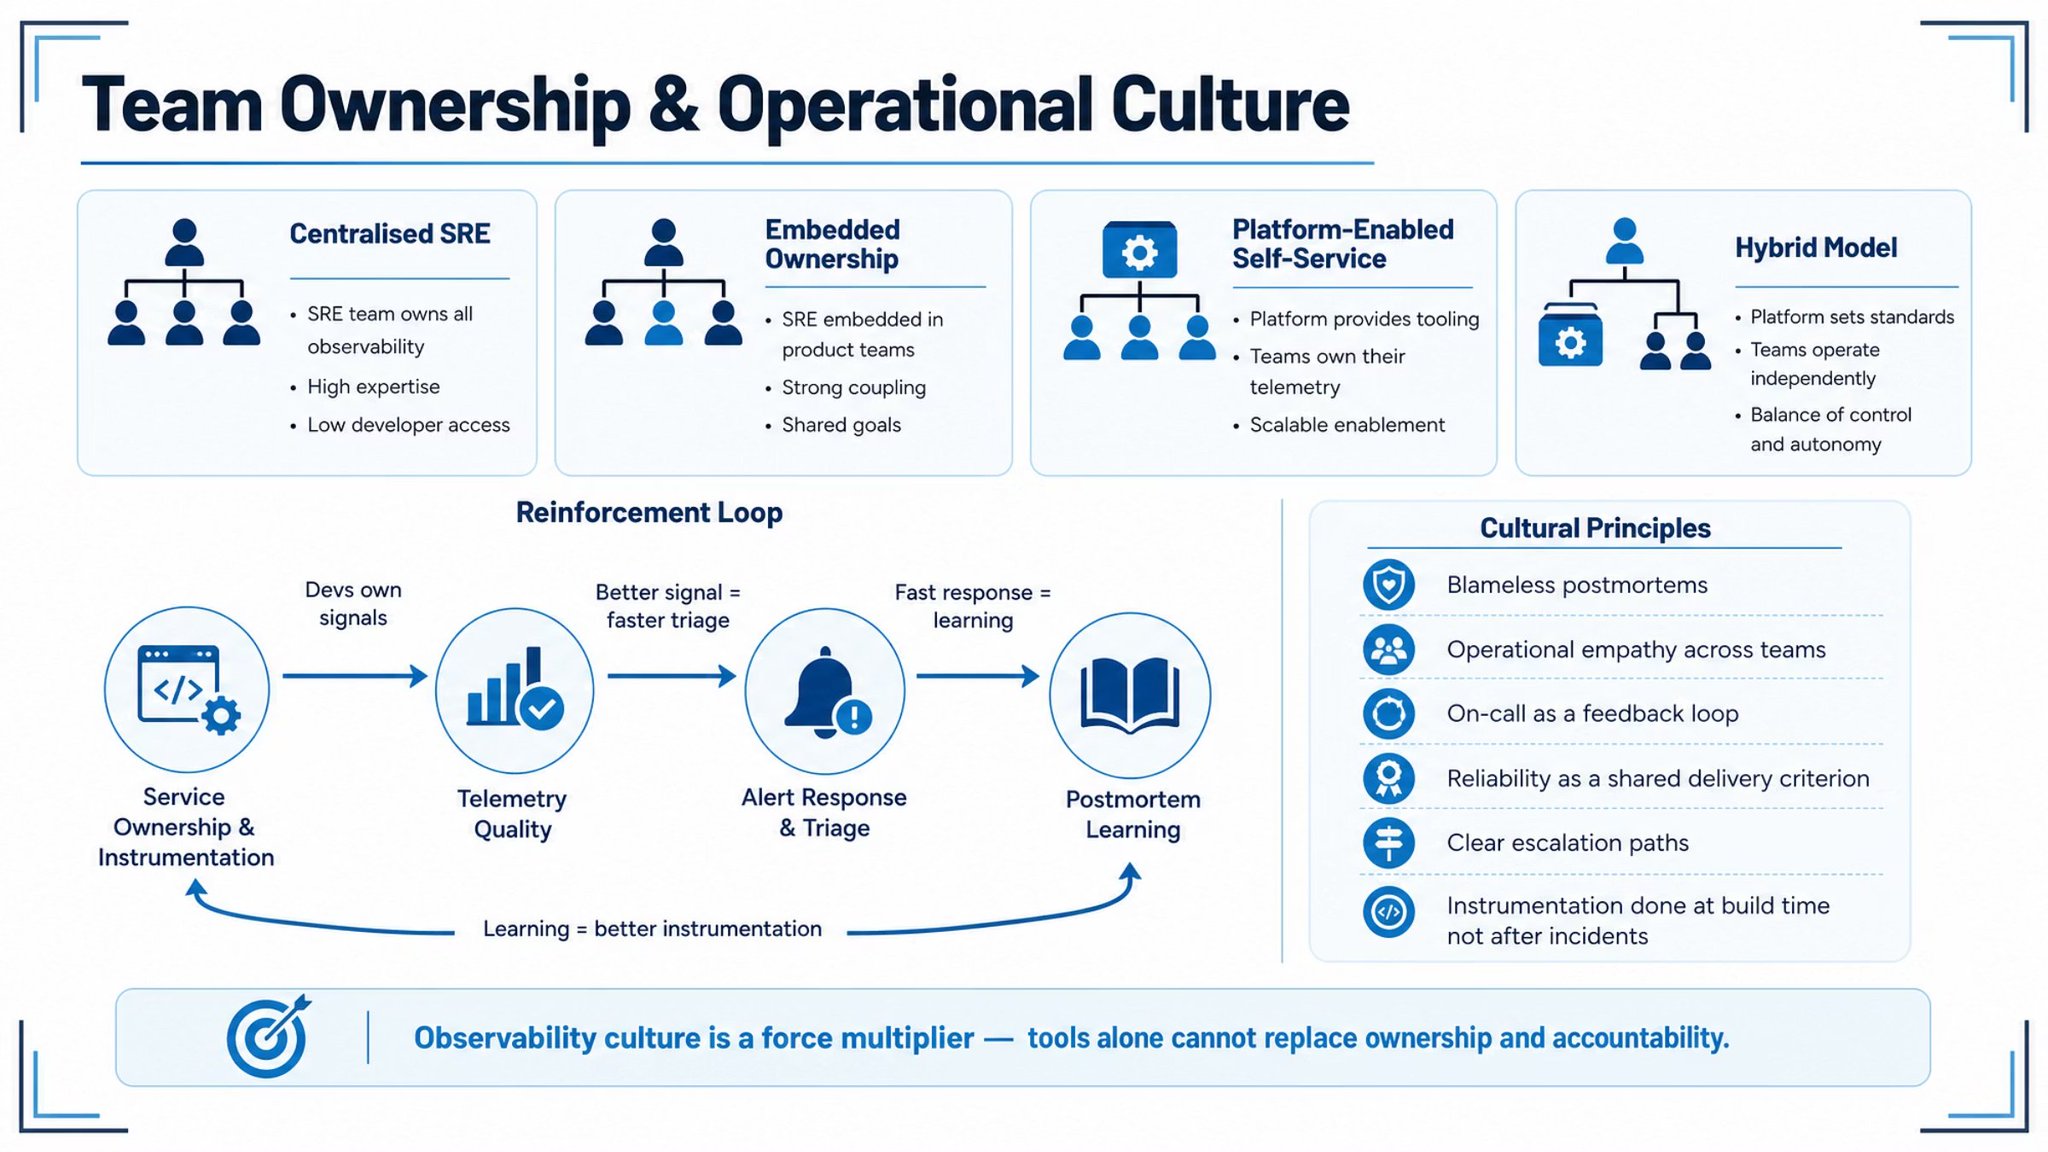
Observability culture is a force multiplier — tools alone cannot replace ownership and accountability.
8. Runbooks & Operational Readiness
Every alert needs a runbook: context, symptoms, likely causes, investigation steps, mitigation, rollback, and escalation. Review quarterly, test rollbacks, run gamedays.
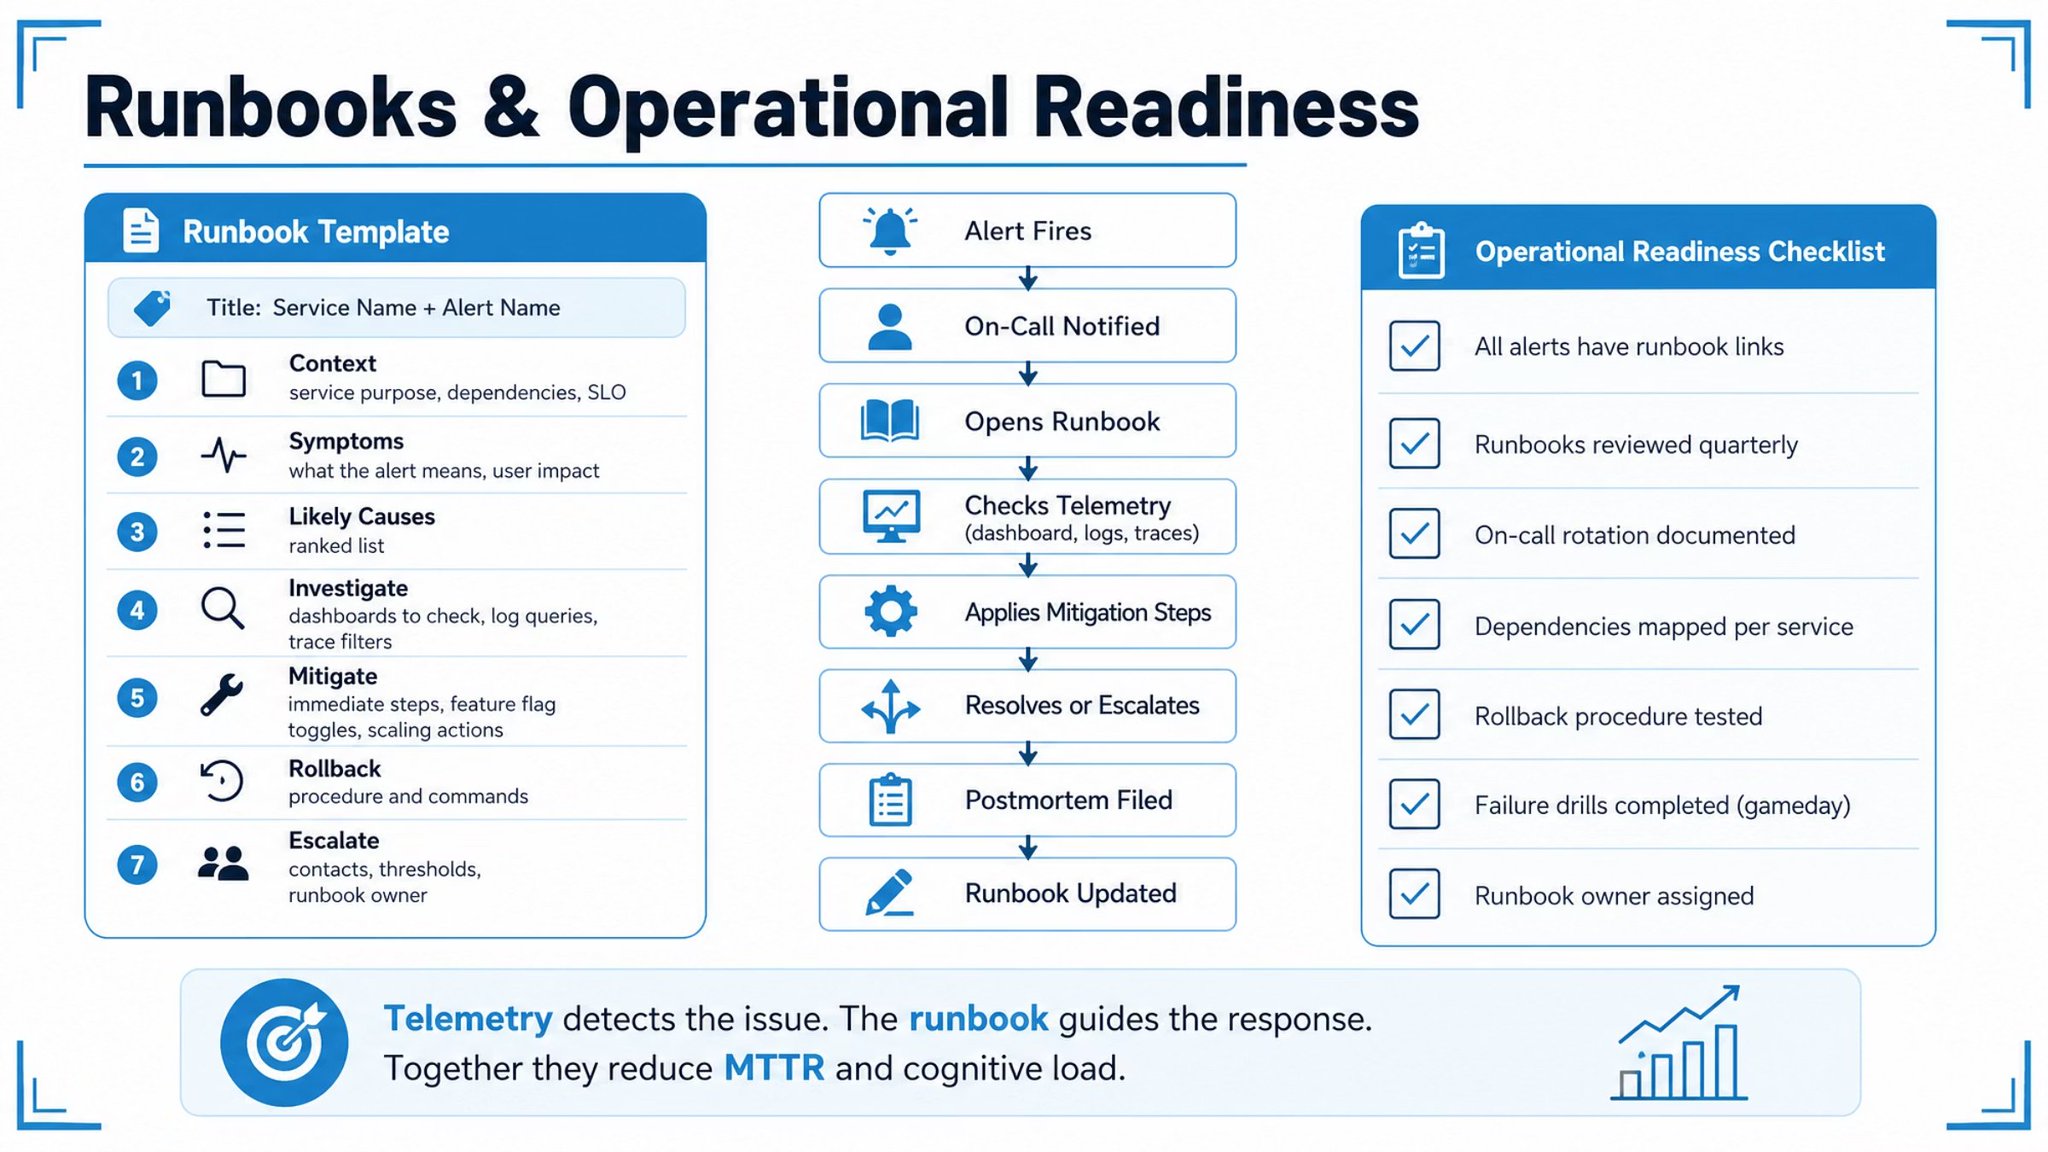
Telemetry detects the issue. The runbook guides the response. Together they reduce MTTR and cognitive load.
9. Observability for AI & LLM Apps
LLM apps need new signals: prompt/model versions, token usage, response quality, hallucination indicators, tool-call success, retrieval relevance, guardrail triggers, and cost per request. Watch for failure modes like bad retrieval, prompt regression, latency spikes, and cost explosions from unbounded token loops.
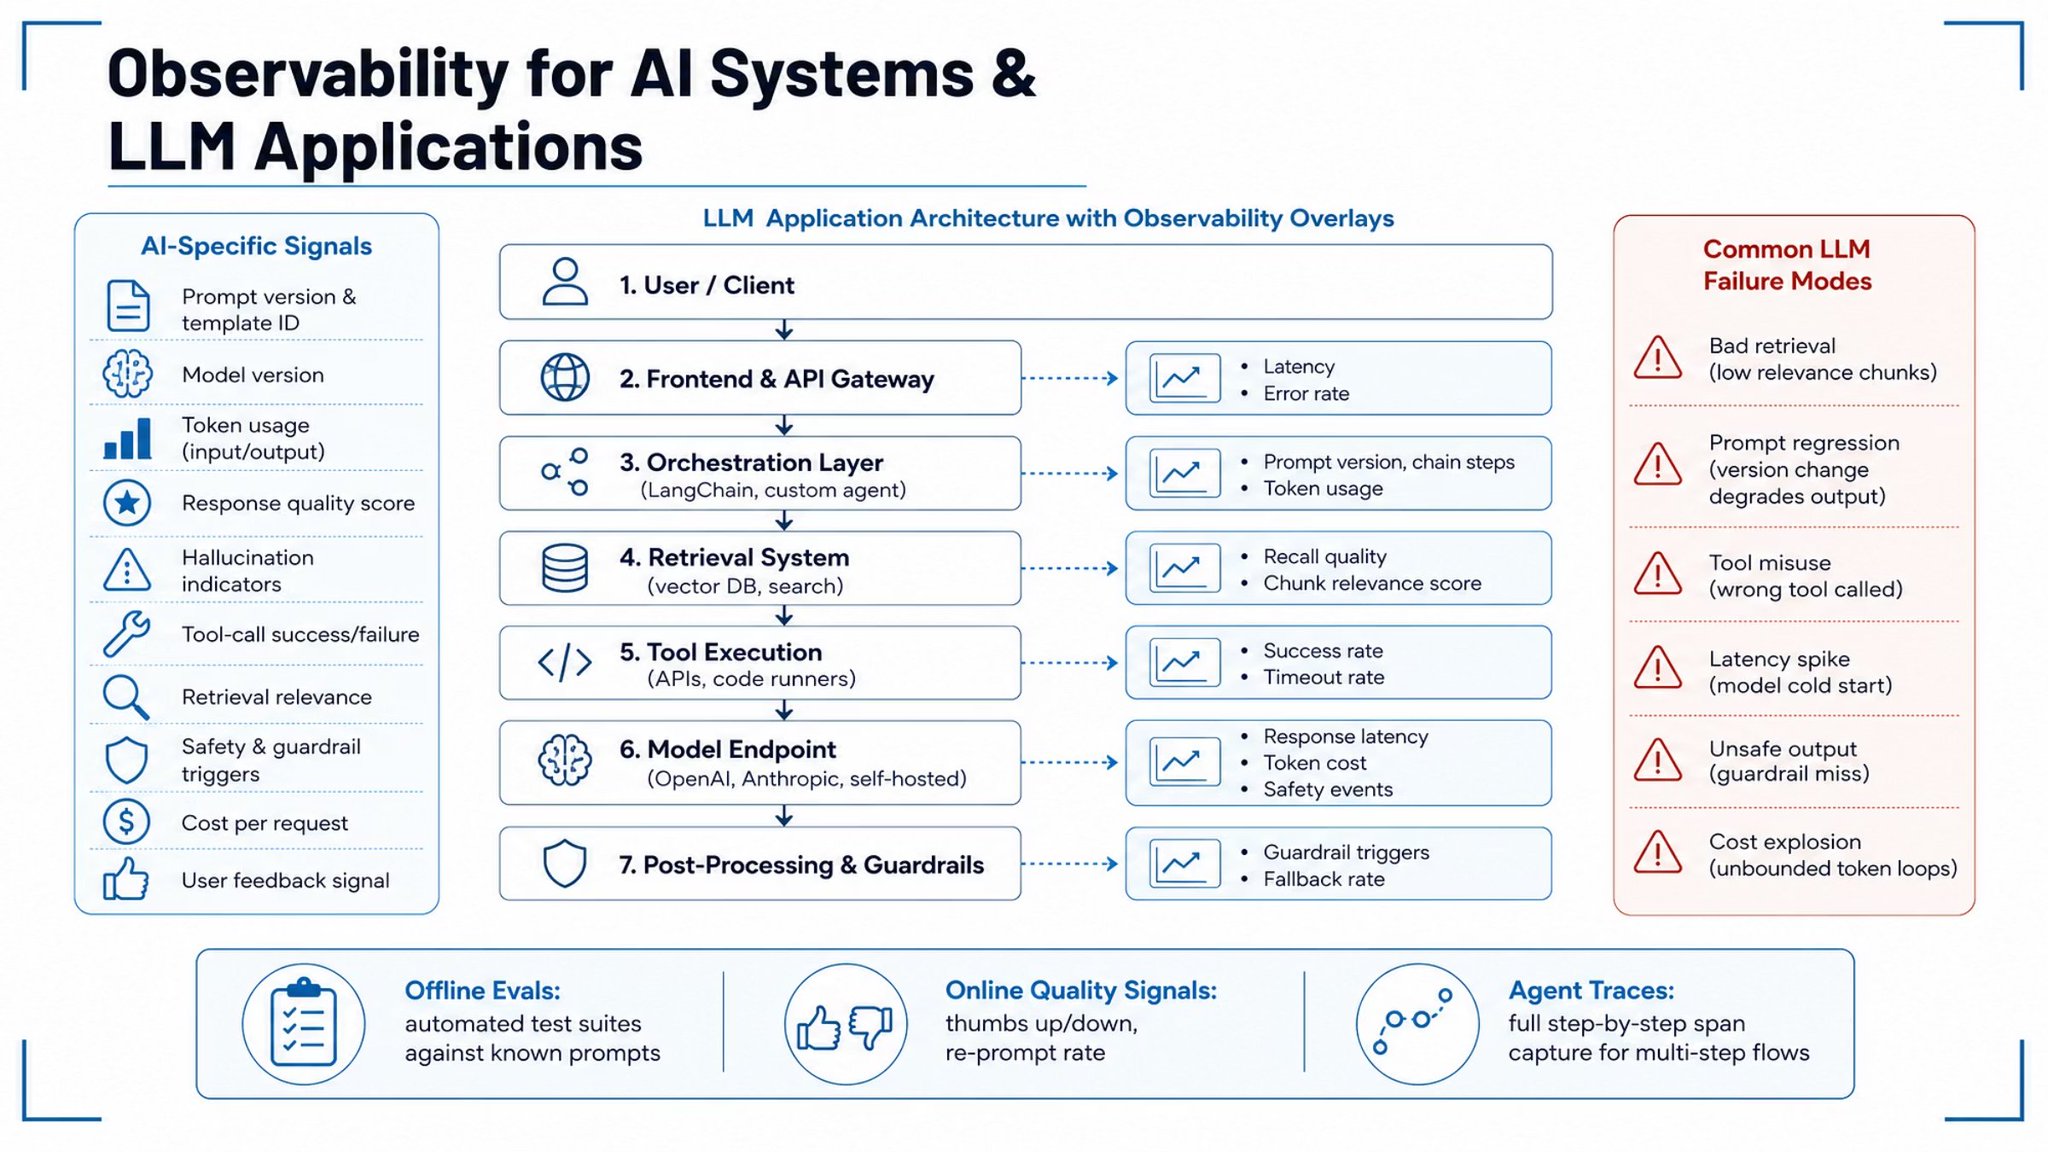
Combine offline evals, online quality signals (thumbs up/down, re-prompt rate), and full agent traces.
Bonus: Architecture & Signal Selection
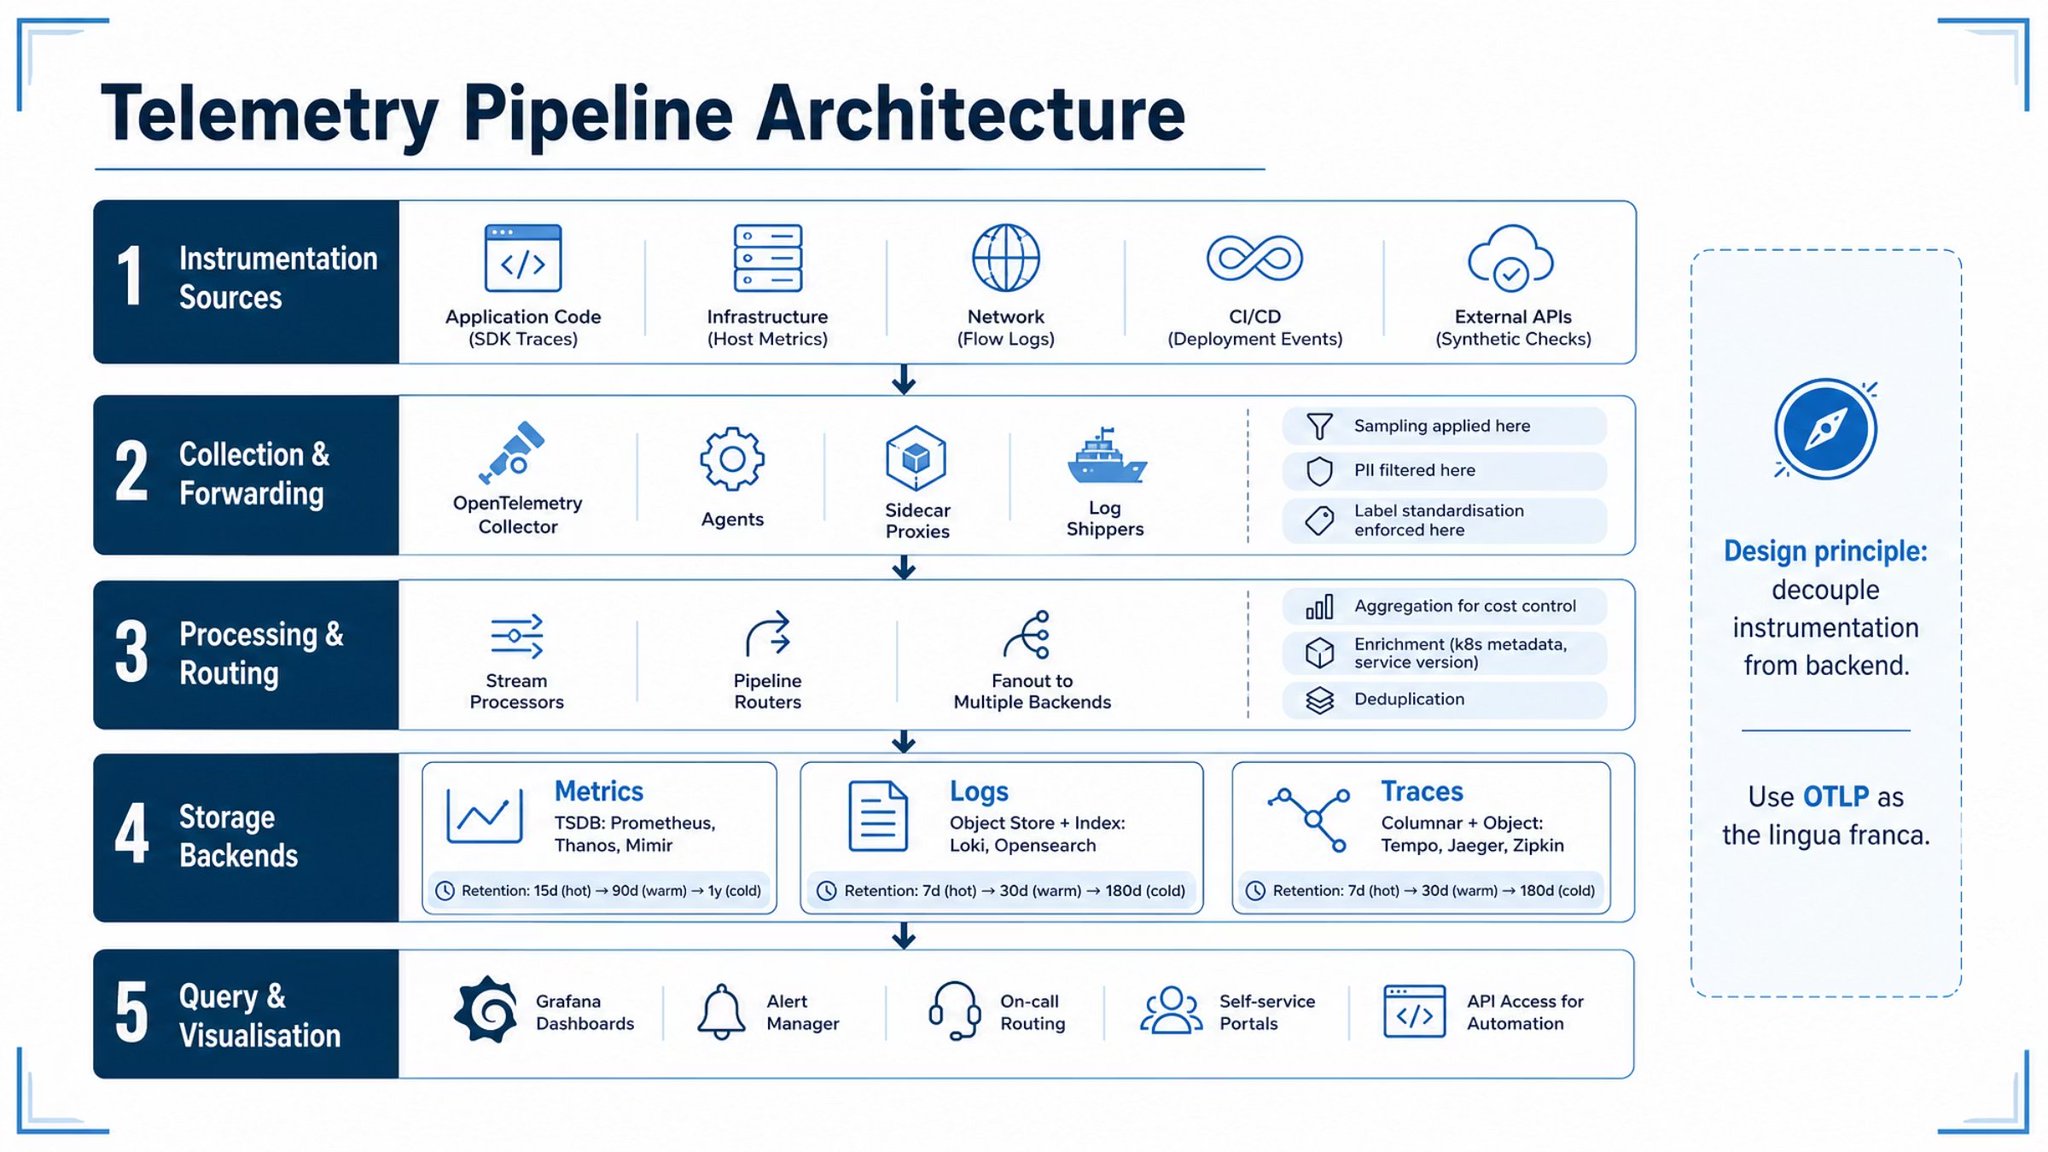
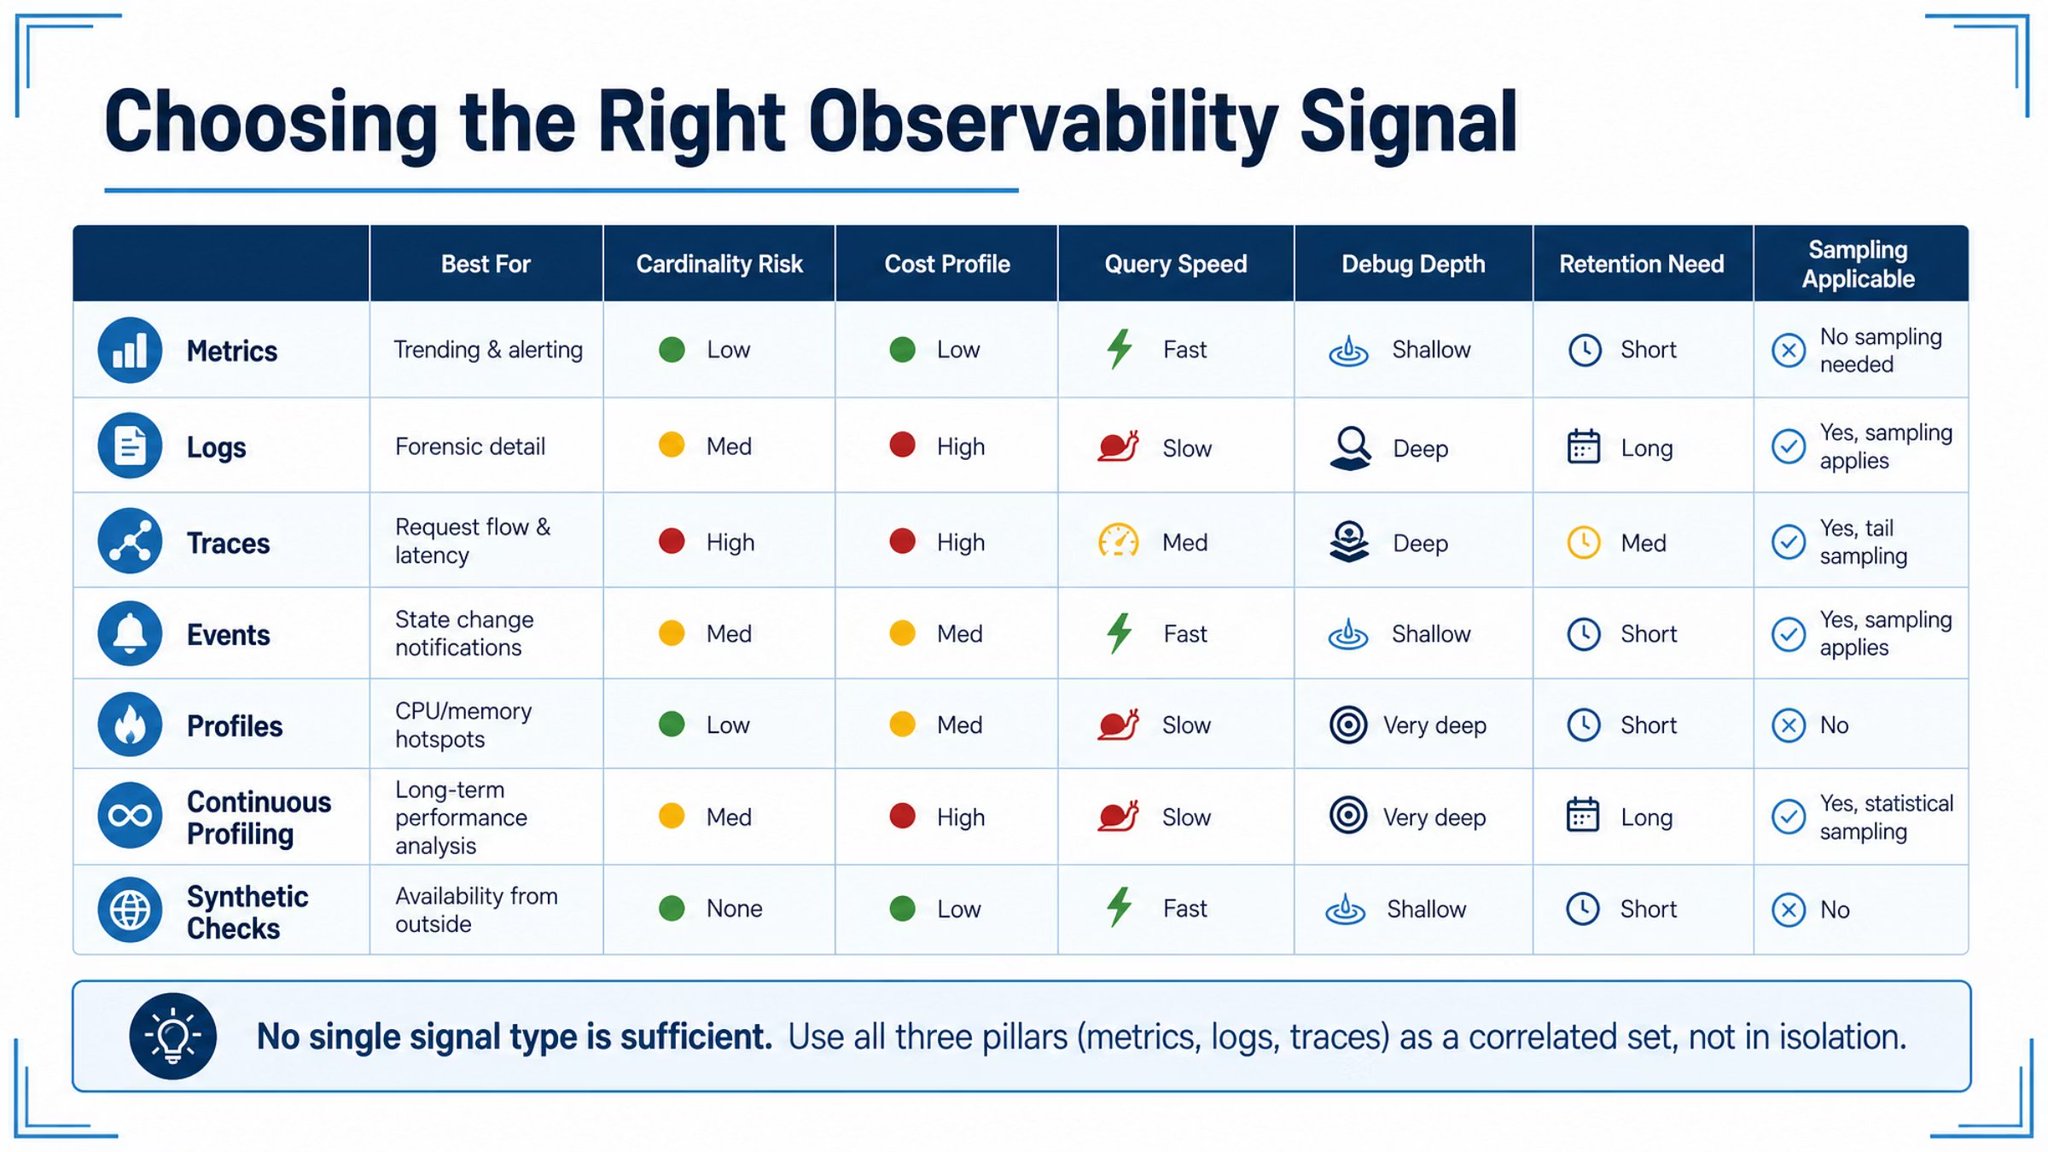
- Pipeline design principle: decouple instrumentation from backend. Use OTLP as the lingua franca.
- No single signal is sufficient — metrics, logs, and traces work as a correlated set.
- Most teams plateau at maturity Stage 2–3. Governance and culture unlock Stage 4–5.
Key Takeaways
- Define SLOs before adding dashboards
- Error budgets drive release decisions
- Instrument at build time, not after incidents
- Control cost with sampling, tiering, and cardinality discipline
- Secure pipelines — PII lives in your logs
- AI assists; humans own the decisions
- Observability maturity is a culture problem, not a tooling problem
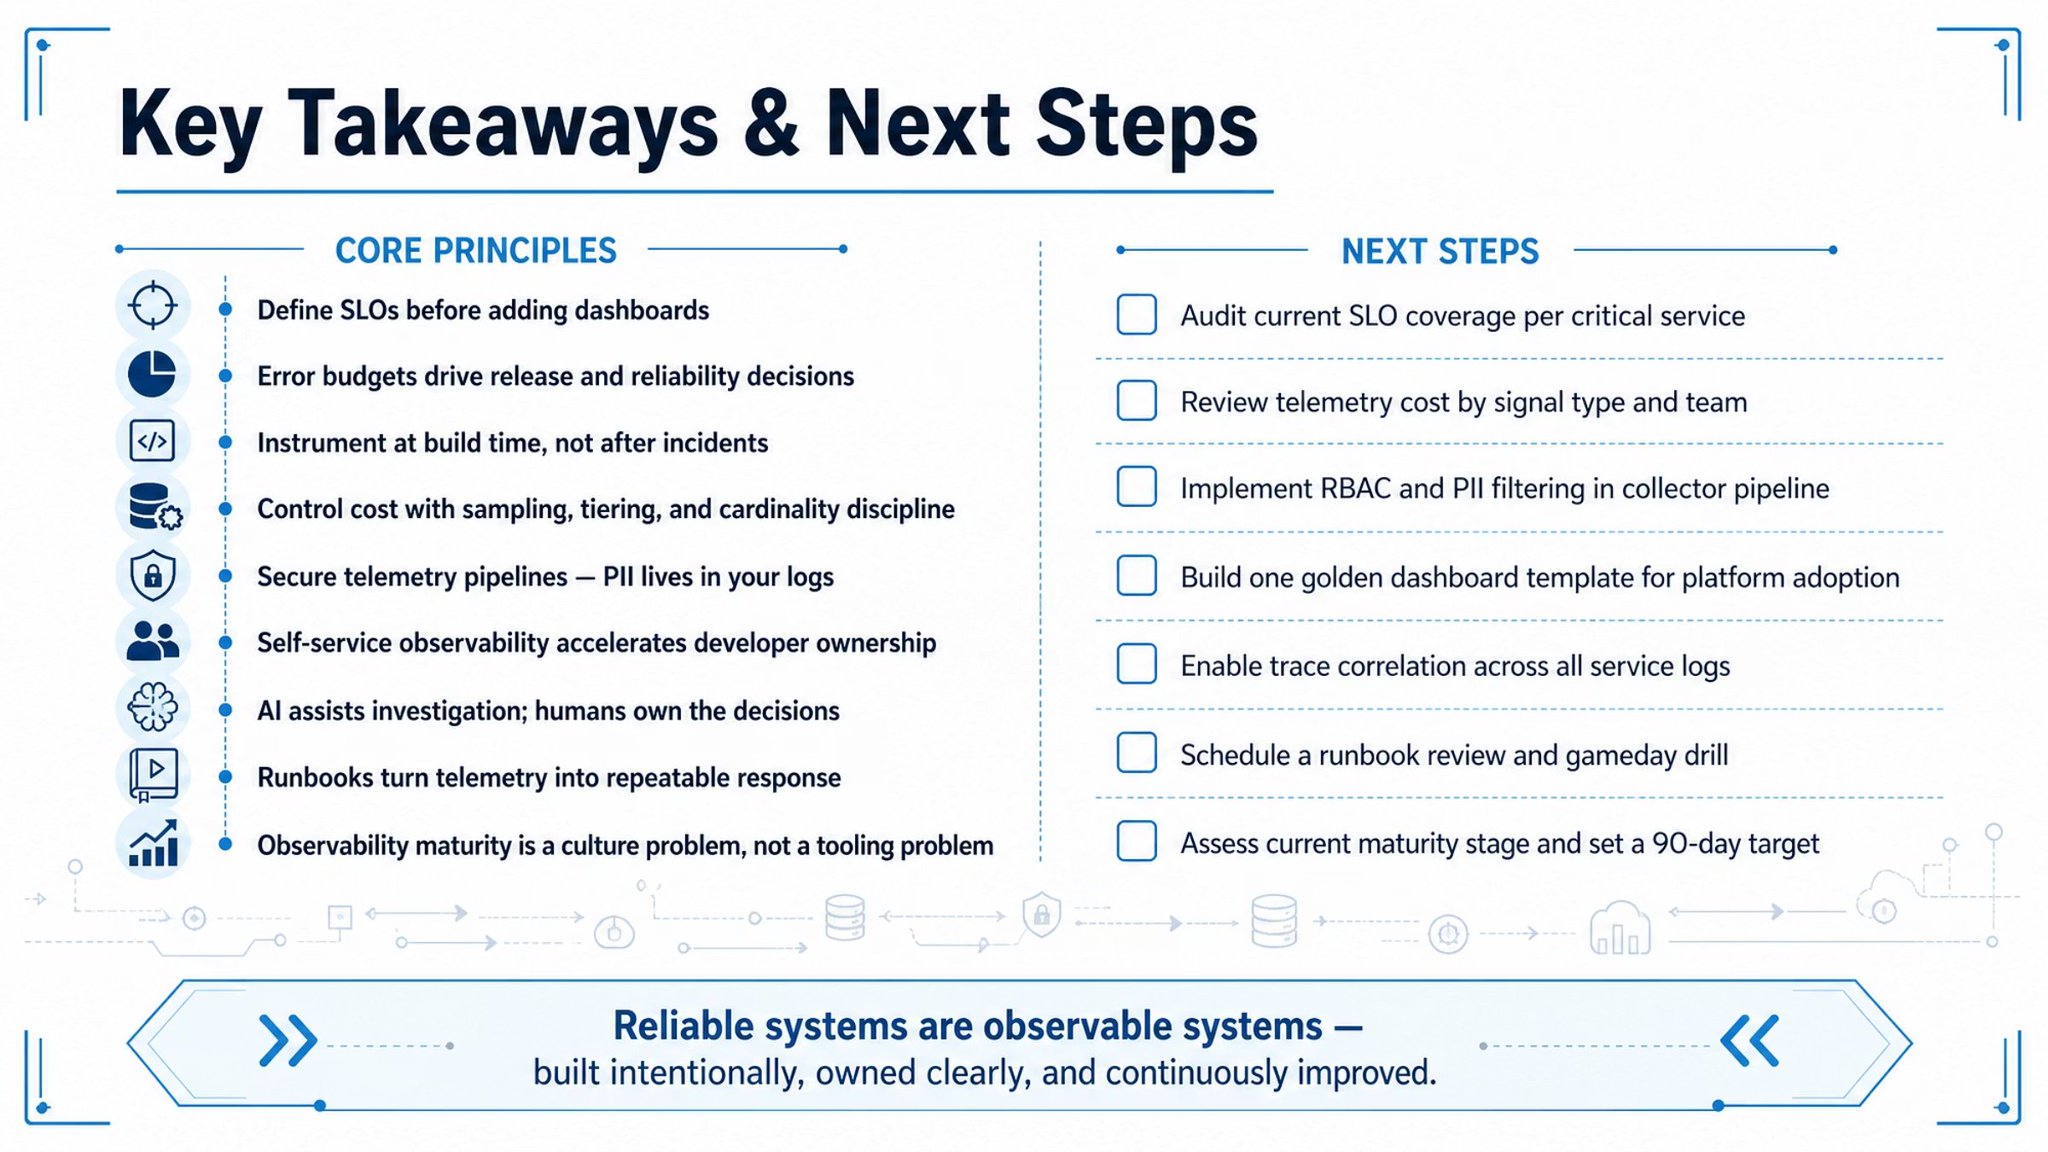
Reliable systems are observable systems - built intentionally, owned clearly, and continuously improved.
Follow Tech Fusionist ☸️
Follow me on other platforms for more DevOps, Cloud, Kubernetes, and AI content.
🔗 Linktree: https://linktr.ee/techfusionist